FinDiff ships as one Docker image. There is no build step, no separate database server to run, and no schema migration to apply by hand, the binary does that on first start.
Quick start
Pull and run the image directly. This is enough to log in, add a database, and try every feature.
Open http://localhost:8080, sign in with the admin credentials above, and add your first database from Databases → Add database.
Important:FINDIFF_MASTER_KEY encrypts every stored connection string. Generate it once, keep it in a secrets manager, and never lose it, a lost key makes stored connections unrecoverable.
Preparing a production deployment
1. Generate and store the master key
openssl rand -base64 32
Store it in your secrets manager (Vault, AWS Secrets Manager, a Kubernetes Secret) and inject it as FINDIFF_MASTER_KEY. Treat it like a database root password.
2. Connect with a dedicated read-only role, not an admin account
FinDiff generates the exact GRANT SELECT statements for your engine directly in the app, under Databases → Read-only role SQL, once you've scanned and mapped at least one table. See The read-only role below for the manual version.
3. Persist the data directory
FinDiff's own SQLite store, encrypted credentials, schema mappings, diff history, and AI attachments all live under /data inside the container. Mount a real named volume, never run production on an ephemeral filesystem.
4. Put a reverse proxy with TLS in front of it
FinDiff does not terminate TLS itself. Run it behind nginx, Caddy, Traefik, or your platform's ingress, and only expose HTTPS externally.
5. Set the bootstrap admin account
FINDIFF_ADMIN_USERNAME and FINDIFF_ADMIN_PASSWORD only take effect if no user exists yet, so it's safe to leave them set on every restart. Change the password after first login, and invite named accounts for everyone else from Settings → Users.
6. Configure retention and alerting
Set a retention window under Settings → Retention appropriate to your compliance requirements, FinDiff exports to an archive before it prunes anything. Add a Slack, Teams, email or webhook channel under Settings → Alerts so the right people see changes as they happen.
Docker Compose
A production compose file. Keep the values in a .env file that is never committed. The image runs as a non-root user (uid 10001) and has its own healthcheck, so you do not need to add one.
Bind mounts: if you mount a host folder on /data instead of using a named volume, it must be writable by uid 10001 (chown 10001:10001 ./data). Dump files live in /data/dumps, so size that volume for them.
The read-only role, by hand
FinDiff's in-app generator does this for you, scoped to whatever you've actually mapped. If you'd rather review the shape of it yourself first, here's the general pattern for Postgres:
CREATE ROLE findiff_reader WITH LOGIN PASSWORD '...';
GRANT CONNECT ON DATABASE your_db TO findiff_reader;
GRANT USAGE ON SCHEMA public TO findiff_reader;
GRANT SELECT ON your_table_1, your_table_2 TO findiff_reader;
MySQL and MariaDB use CREATE USER ... IDENTIFIED BY and one GRANT SELECT ON db.table per table. SQL Server uses CREATE LOGIN and CREATE USER ... FOR LOGIN. Oracle uses CREATE USER ... IDENTIFIED BY plus GRANT CREATE SESSION. SQLite has no role system at all, restrict access with file permissions instead.
On top of the database-level role, FinDiff runs a statement guard that rejects anything that isn't SELECT, and opens read-only transactions where the driver supports it. The role is defense in depth, not the only control.
Environment variables
These are all the variables FinDiff reads. Everything else is configured in the app and applies immediately, without a restart.
Variable
Required
Default
Purpose
FINDIFF_MASTER_KEY
Yes
—
Base64-encoded 32-byte key. Encrypts stored connection strings and the dump files at rest. FinDiff refuses to start without it. Losing it makes both unrecoverable.
FINDIFF_ADMIN_USERNAME
No
—
Bootstrap admin, created only if no user exists. Safe to leave set.
FINDIFF_ADMIN_PASSWORD
No
—
Bootstrap admin password. Change it after the first sign-in.
FINDIFF_PORT
No
8080
Port the server listens on inside the container.
FINDIFF_DATA_DIR
No
/data in the image, ./data locally
Where findiff.db, dump files (dumps/) and Copilot uploads live. Always mount it.
FINDIFF_PUBLIC_URL
No
—
The address people use, for example https://findiff.example.com. Used in share-link URLs and as the single sign-on redirect address. Set it whenever FinDiff is behind a proxy.
FINDIFF_METRICS_TOKEN
No
unset (metrics off)
Bearer token that enables GET /api/metrics for Prometheus. Unset means the endpoint returns 404.
FINDIFF_MAX_UPLOAD_GB
No
10
Largest dump file that can be uploaded, in GB.
FINDIFF_UPDATE_CHECK
No
true
Set to false to stop FinDiff from checking for new releases (air-gapped or no-outbound networks). The app then never mentions updates.
FINDIFF_UPDATE_URL
No
https://findiff.fr/latest.json
Where the release manifest is read from. Change it only if you mirror the manifest internally.
FINDIFF_SECRETS_DIR
No
/run/secrets
Directory that ${file:NAME} references in connection strings are read from.
FINDIFF_SECRET_*
No
—
Variables that ${env:NAME} references may read. Only names starting with FINDIFF_SECRET_ are readable, on purpose.
Configured in the app (Settings), not by variable
Where
What
Databases
Monitored databases, snapshot interval, the read-only role generator, test connection, scan metadata
Dumps → Write access
The separate write connection each database needs before it can be an import target
Weekly or monthly PDF by email (needs an SMTP channel)
Settings → Retention, Backup, AI Copilot, AI daily summary
History window with export before prune, backup download, provider and daily digest
Dumps: export and import New
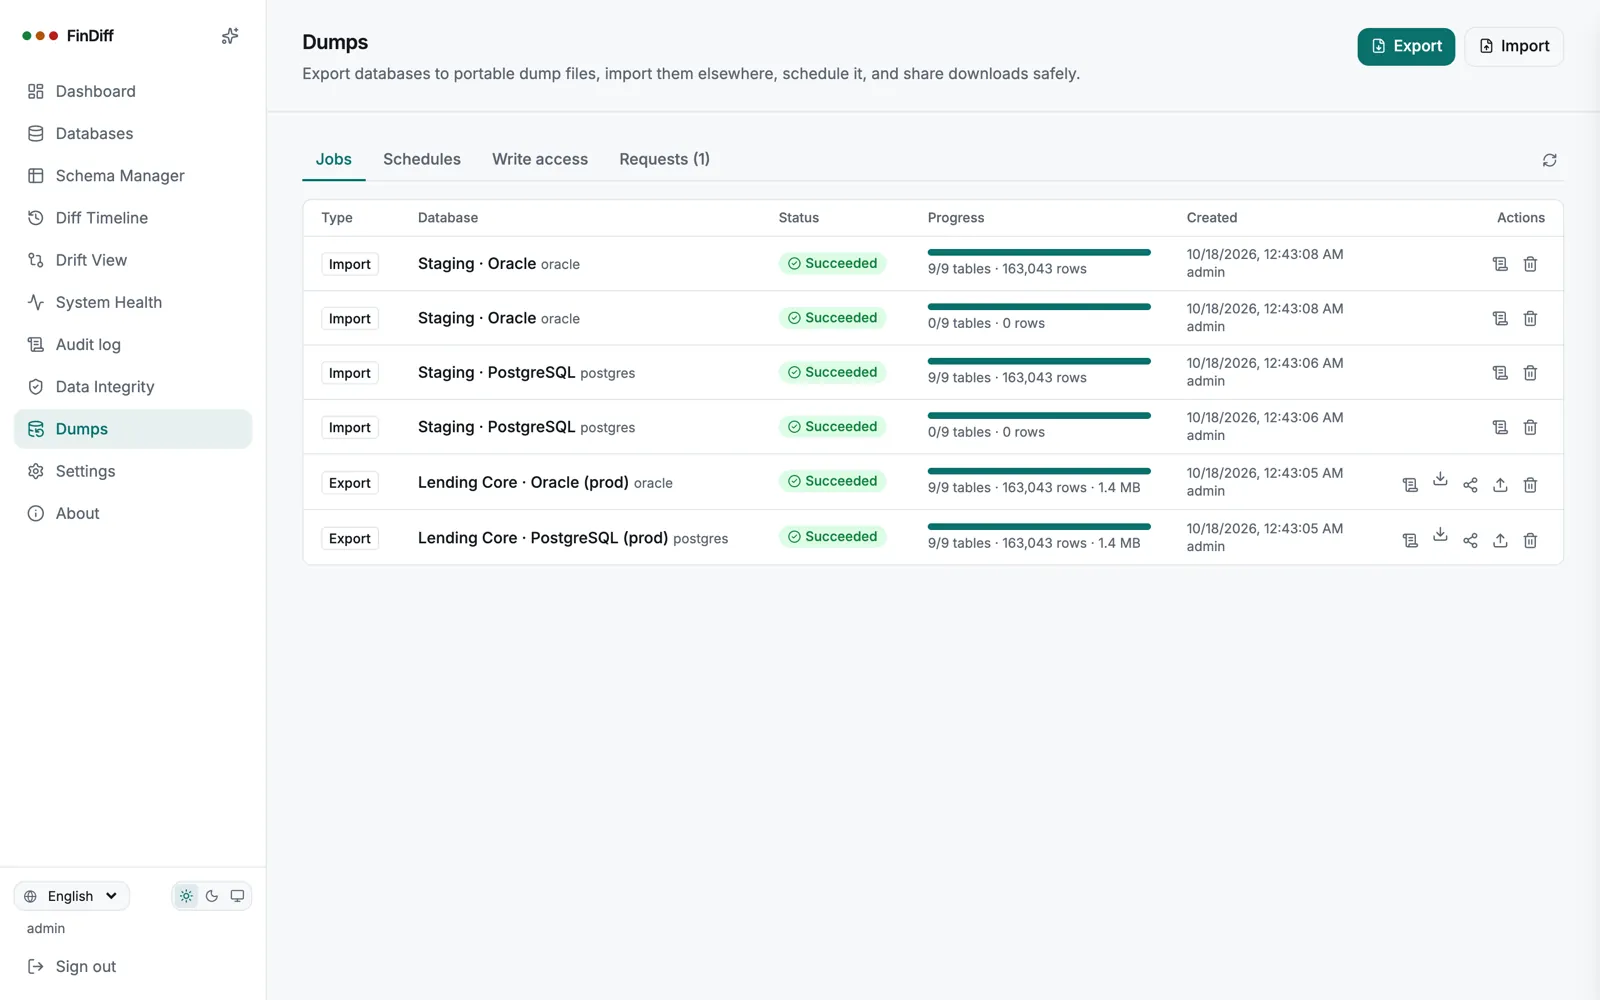
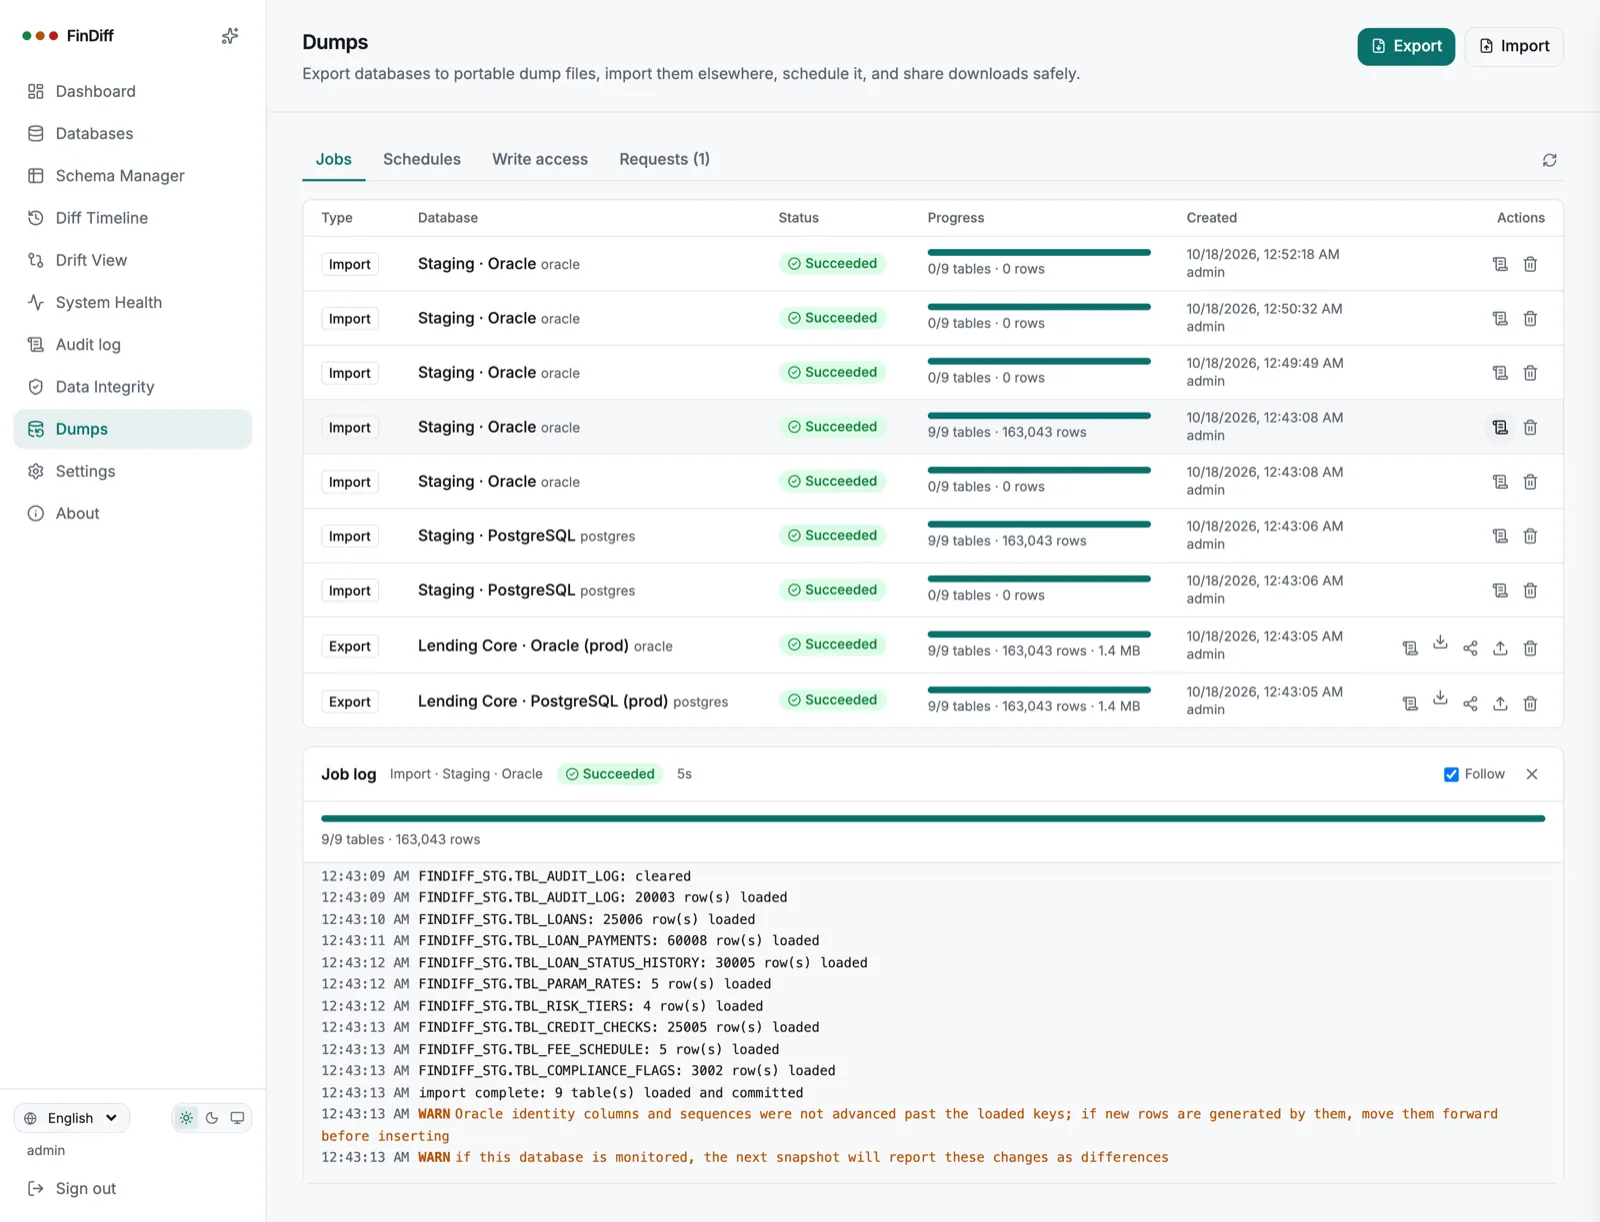
The Dumps page (administrators) exports a database to a portable .fdump file, imports it elsewhere, runs both on a schedule and shares downloads through expiring links. Progress and logs stream live and are stored with the job, so closing the tab loses nothing.
What a dump is
gzip-compressed NDJSON with typed values and a trailer of row counts. A truncated or corrupted file is rejected before anything is written.
Stored under $FINDIFF_DATA_DIR/dumps, encrypted at rest with a key derived from FINDIFF_MASTER_KEY. A download or share link delivers the plain .fdump, which another FinDiff instance can upload and import.
Import is same-engine: a PostgreSQL dump loads into PostgreSQL, an Oracle dump into Oracle. Cross-engine type mapping is not supported.
Export
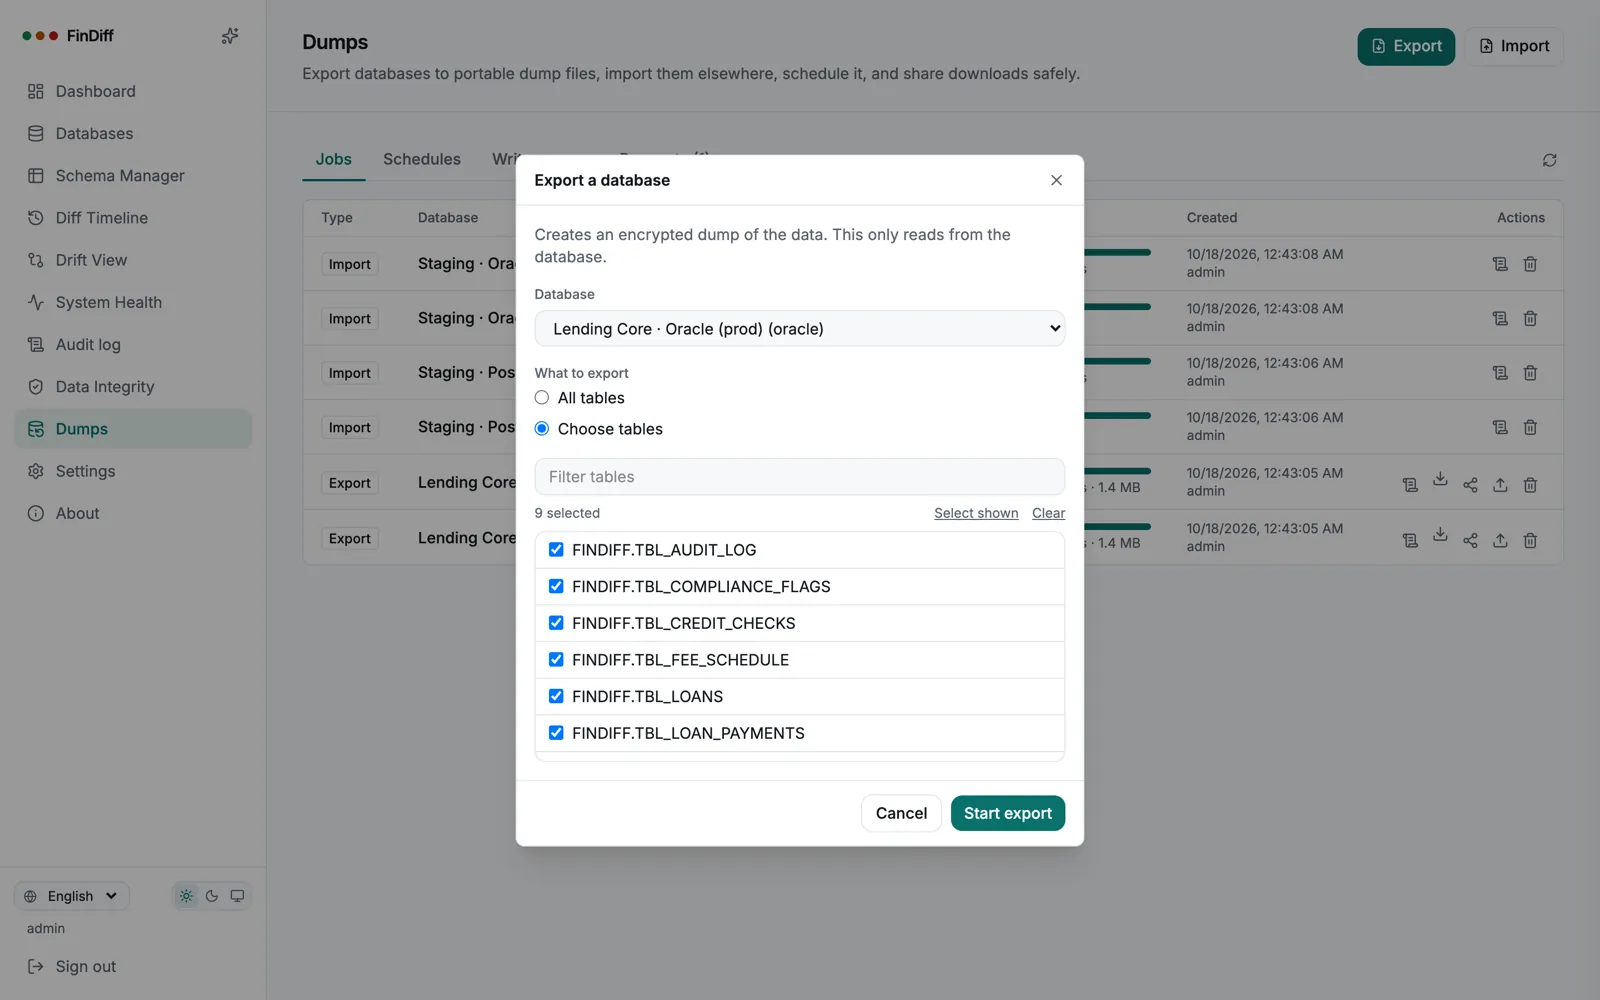
Dumps → Export, choose the database, then all tables or a selection. Export only reads, through the same read-only connection as monitoring, so it needs no extra setup. Tables are written parents first, so foreign keys are satisfied on import. A table without a primary key is read in one pass and the log warns about it.
On Oracle the list shows OWNER.TABLE. If the monitoring user can see several schemas, select the tables of the one you want, so the dump holds a single schema.
Import
Importing writes, so it is deliberately hard to do by accident.
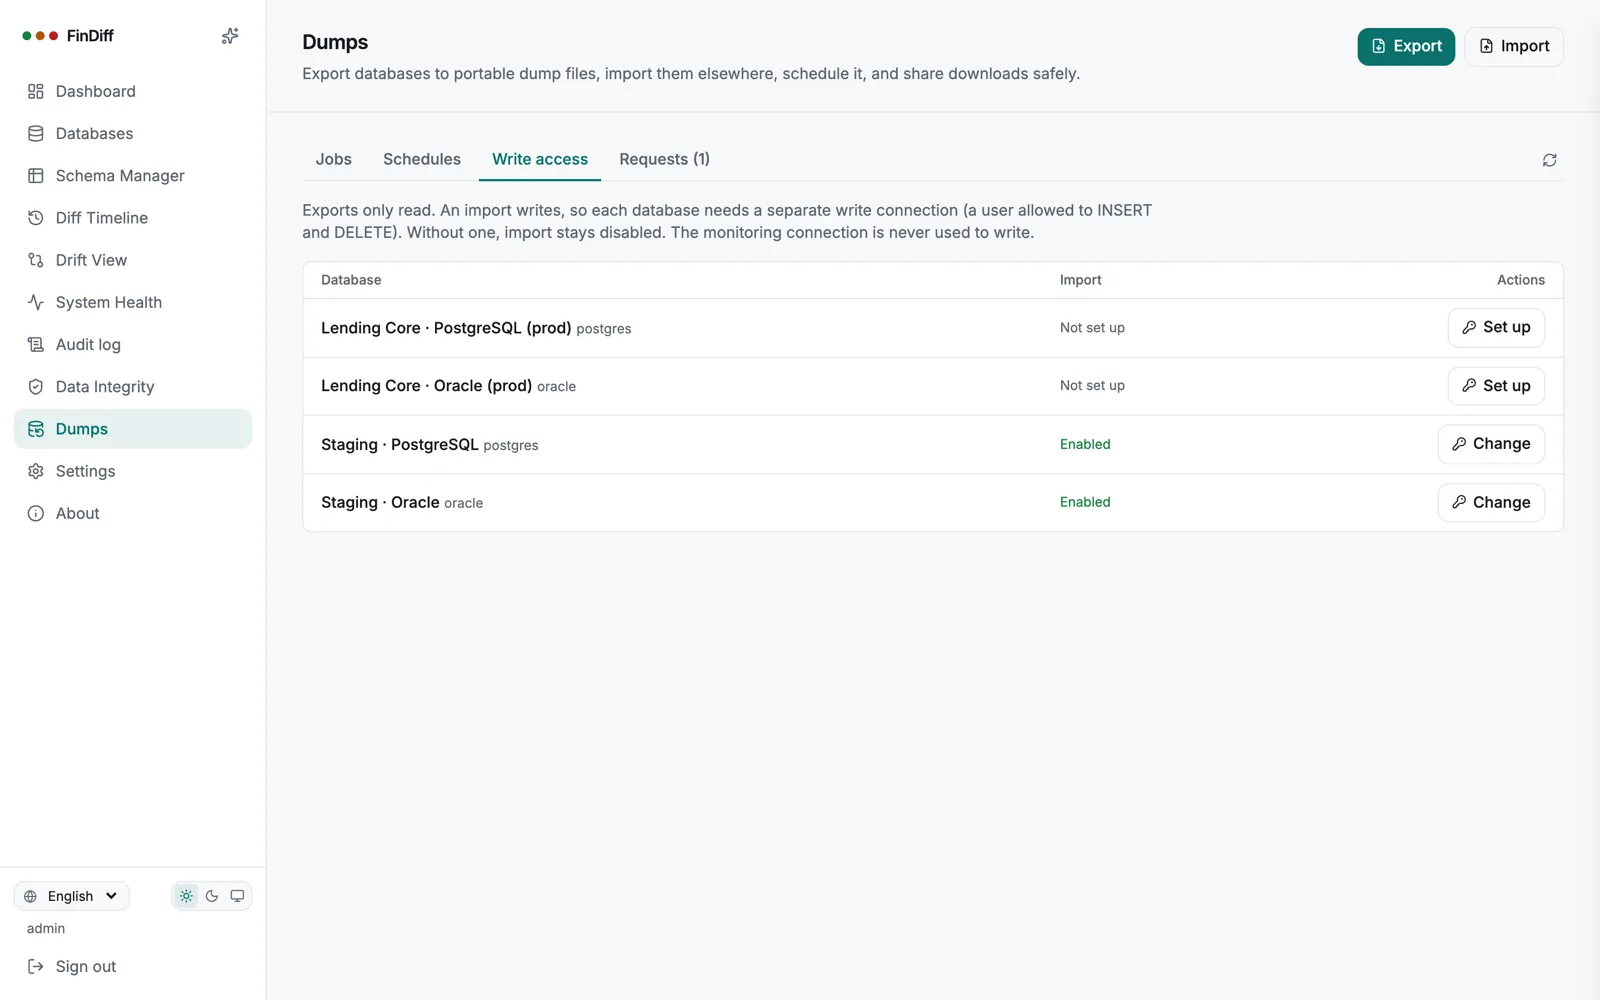
Give the target database a write connection (Dumps → Write access). Without one, import is disabled. The monitoring connection is never used to write.
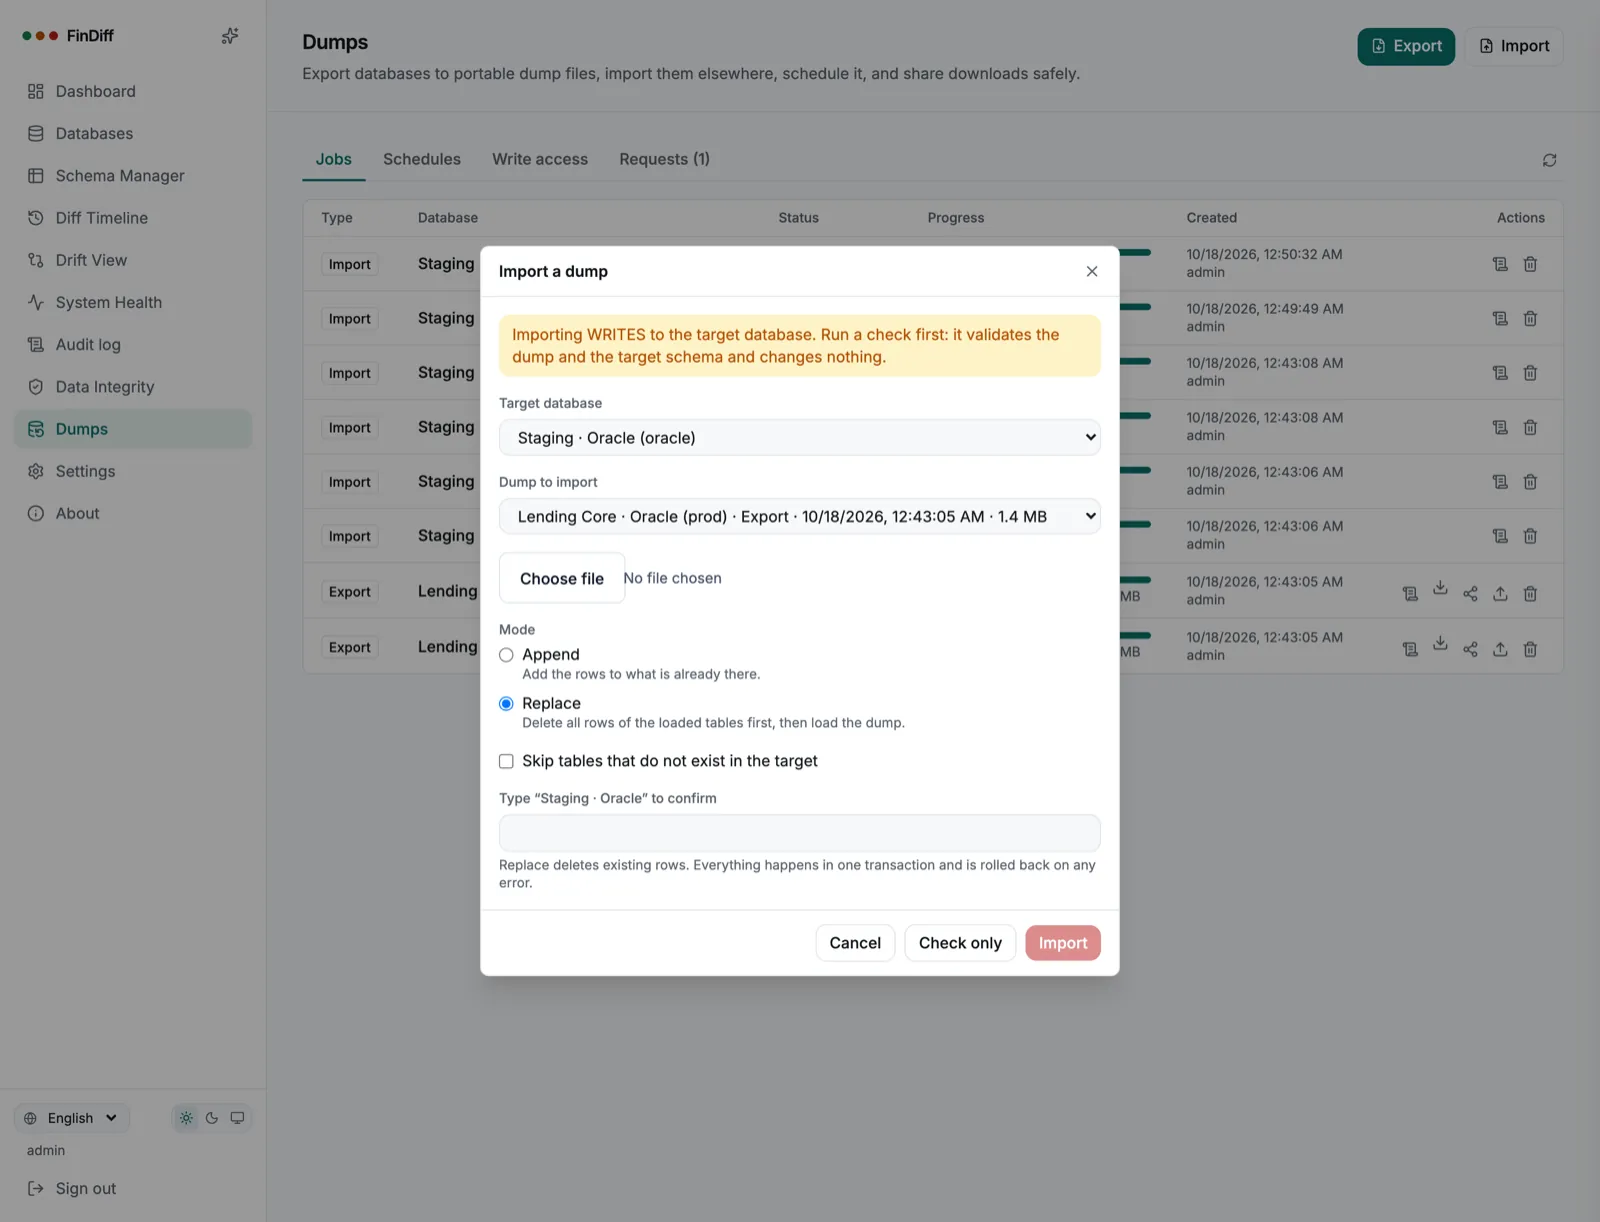
Dumps → Import: choose the target, the dump (a stored export, or upload a file) and the mode: Append adds rows; Replace deletes the loaded tables’ rows first, and asks you to type the database name.
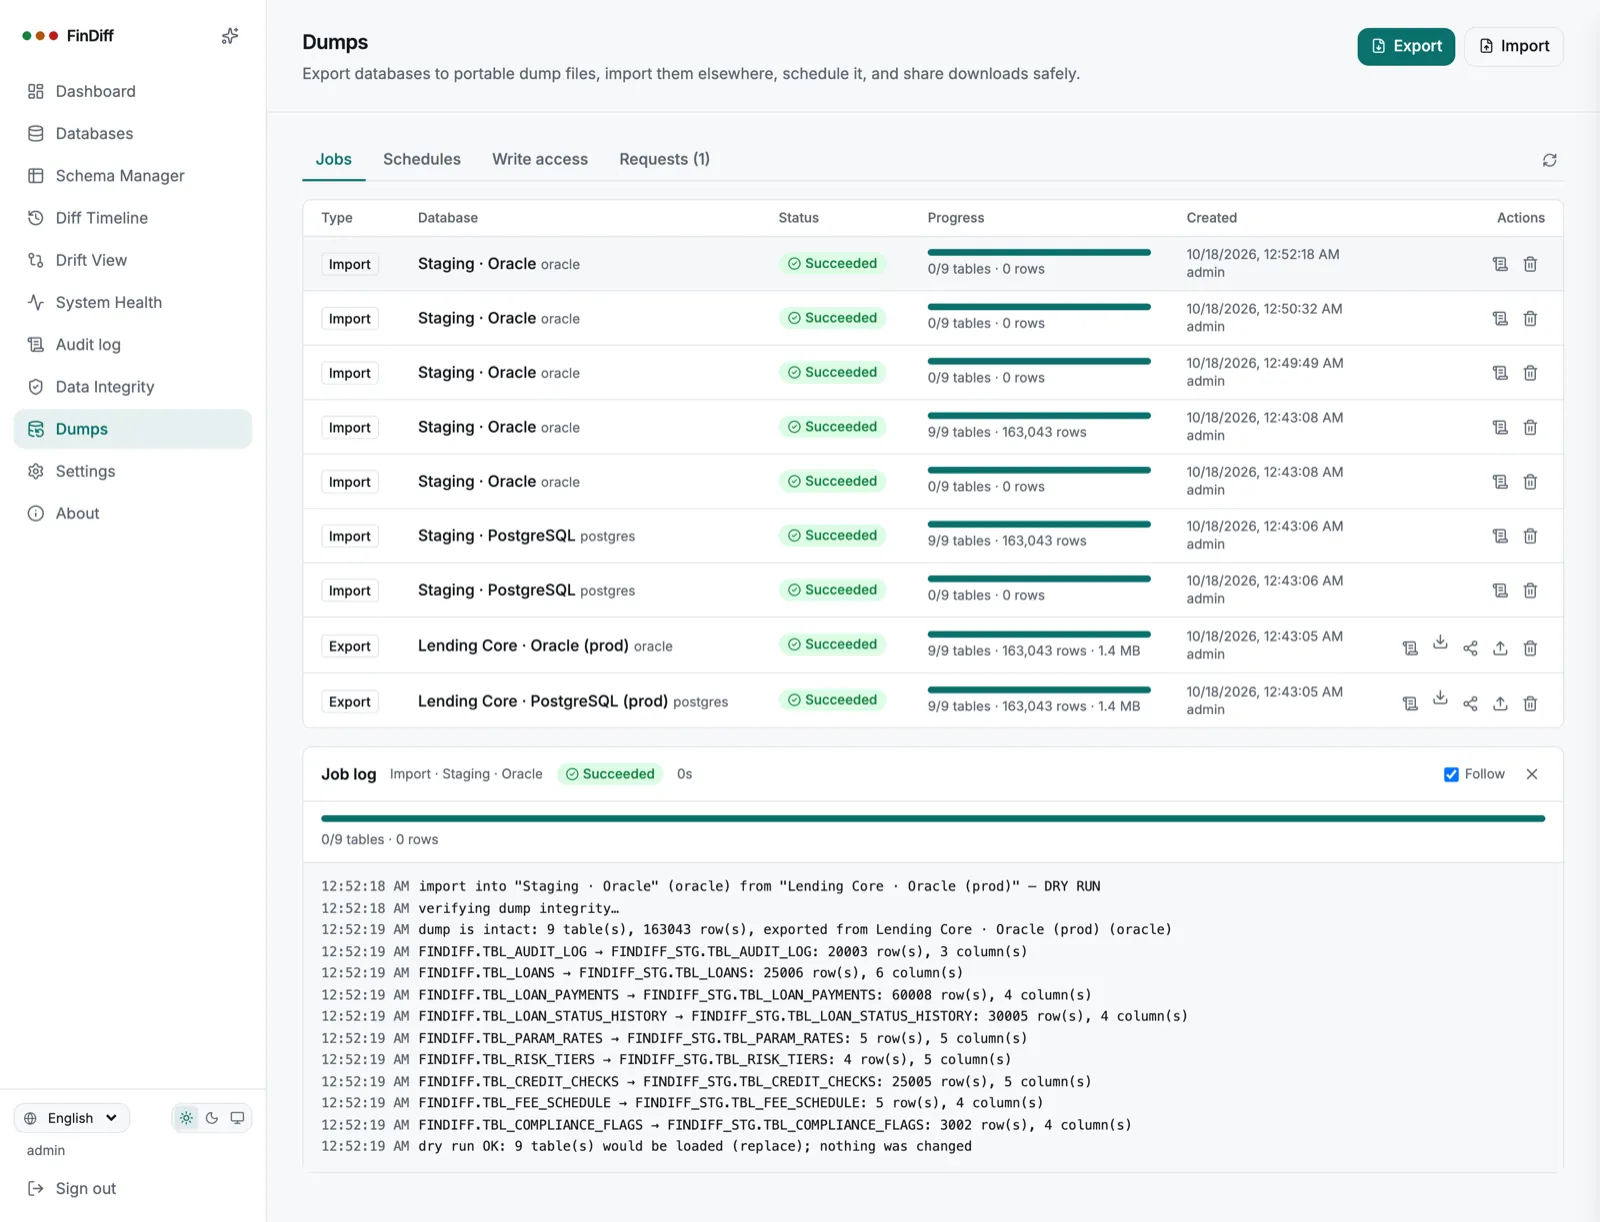
Press Check only first. The dry run verifies the whole dump and compares it with the target schema (missing tables or columns, load order, two dump tables resolving to one target) and changes nothing.
Press Import. It runs in one transaction: any error rolls everything back. The live log shows each table.
By default it loads into existing tables. Tick Create tables that do not exist (API create_missing: true, also on import schedules) to create the missing ones first from the definitions saved in the dump, see below. “Skip tables that do not exist in the target” instead lets a partial target through.
PostgreSQL sequences are advanced after loading explicit keys, and SQL Server identity counters move on by themselves. On Oracle they are not advanced (that needs DDL, which would break the all-or-nothing guarantee); the log says so. Move them forward yourself before inserting new rows.
If the target is monitored, the next snapshot reports the imported changes as differences.
Creating missing tables
An export saves each table’s definition, read from the engine’s catalog (a SELECT-only role is enough). With Create tables that do not exist an import creates the tables the target lacks, loads them, then adds their indexes and foreign keys. The target can be completely empty. Same engine only: the dry run refuses a dump from another engine, and a dump made before this feature has no definitions, so export it again.
Carried over: column types with length, precision and scale, NOT NULL, defaults, identity and auto-increment, primary and unique keys, check constraints (PostgreSQL, SQL Server, Oracle), secondary indexes and foreign keys.
Not carried over: tablespaces and storage, partitioning, triggers, user-defined types, functional, columnstore and spatial indexes, MySQL and MariaDB check constraints. Generated columns become plain columns, because their values come from the dump.
Names: Oracle creates tables in the connected user’s schema, MySQL and MariaDB in the connected database, PostgreSQL and SQL Server in the dump’s schema (it must exist).
Failure policy: PostgreSQL and SQL Server create tables inside the import transaction, so a failure leaves nothing behind. MySQL, MariaDB and Oracle commit a CREATE TABLE immediately, so the import creates the tables first and drops them again if the load fails; the log says so. An index that cannot be built after the data is loaded is reported as a warning.
Identity: serial and identity columns are created GENERATED BY DEFAULT AS IDENTITY so the dump’s keys load. On Oracle, tables created this way are moved past the loaded keys automatically; for tables that already existed you still do it yourself.
Write connection per engine
Create a dedicated user for each import target. These are patterns: review them with your DBA and narrow them to your schema. Then open Dumps → Write access → Set up and paste the connection string; FinDiff tests it before saving and stores it encrypted. Secret references work here too.
PostgreSQL
CREATE ROLE findiff_writer WITH LOGIN PASSWORD '...';
GRANT CONNECT ON DATABASE staging TO findiff_writer;
GRANT USAGE ON SCHEMA public TO findiff_writer;
GRANT SELECT, INSERT, DELETE ON ALL TABLES IN SCHEMA public TO findiff_writer;
-- sequences are advanced after loading explicit keys, which needs UPDATE
GRANT USAGE, UPDATE ON ALL SEQUENCES IN SCHEMA public TO findiff_writer;

-- connection string
postgres://findiff_writer:...@db:5432/staging?sslmode=verify-full&sslrootcert=/path/ca.crt
MySQL and MariaDB
CREATE USER 'findiff_writer'@'%' IDENTIFIED BY '...';
GRANT SELECT, INSERT, DELETE ON staging.* TO 'findiff_writer'@'%';

-- connection string
findiff_writer:...@tcp(db:3306)/staging
SQL Server
CREATE LOGIN findiff_writer WITH PASSWORD = '...';
USE staging;
CREATE USER findiff_writer FOR LOGIN findiff_writer;
ALTER ROLE db_datareader ADD MEMBER findiff_writer;
ALTER ROLE db_datawriter ADD MEMBER findiff_writer;
-- loading explicit keys into IDENTITY columns requires ALTER on the table
GRANT ALTER ON SCHEMA::dbo TO findiff_writer;

-- connection string
sqlserver://findiff_writer:...@db:1433?database=staging
Oracle
-- simplest: use the schema owner of the target tables. Otherwise:
CREATE USER findiff_writer IDENTIFIED BY "...";
GRANT CREATE SESSION TO findiff_writer;
GRANT SELECT, INSERT, DELETE ON STAGING.TBL_LOANS TO findiff_writer;  -- one per table

-- connection string (service name)
oracle://findiff_writer:...@db:1521/FREEPDB1
SQLite
The path of the database file, which must be writable by the FinDiff container.
Schedules, sharing and requests
Schedules
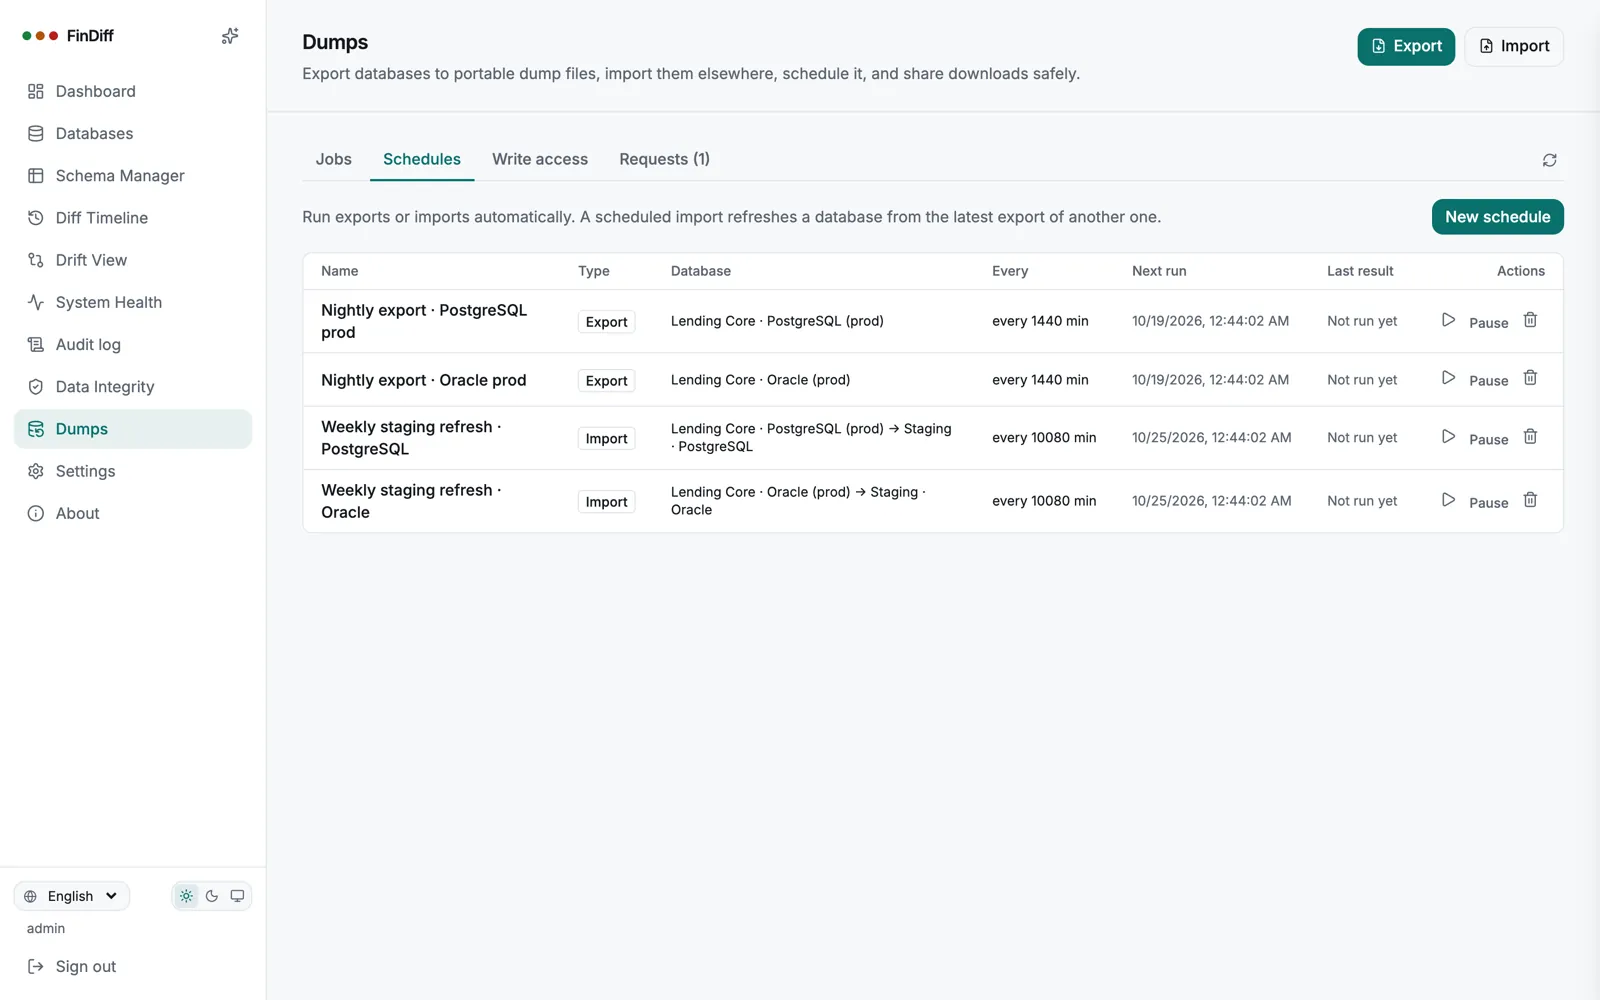
Dumps → Schedules → New schedule. An export schedule runs every N minutes (minimum 5) and keeps the last K dumps. An import schedule refreshes a target from the latest export of another database, for example production to staging every week; a scheduled replace needs the same typed confirmation as a manual one. The last result of each schedule is shown, and you can run now or pause.
Share links
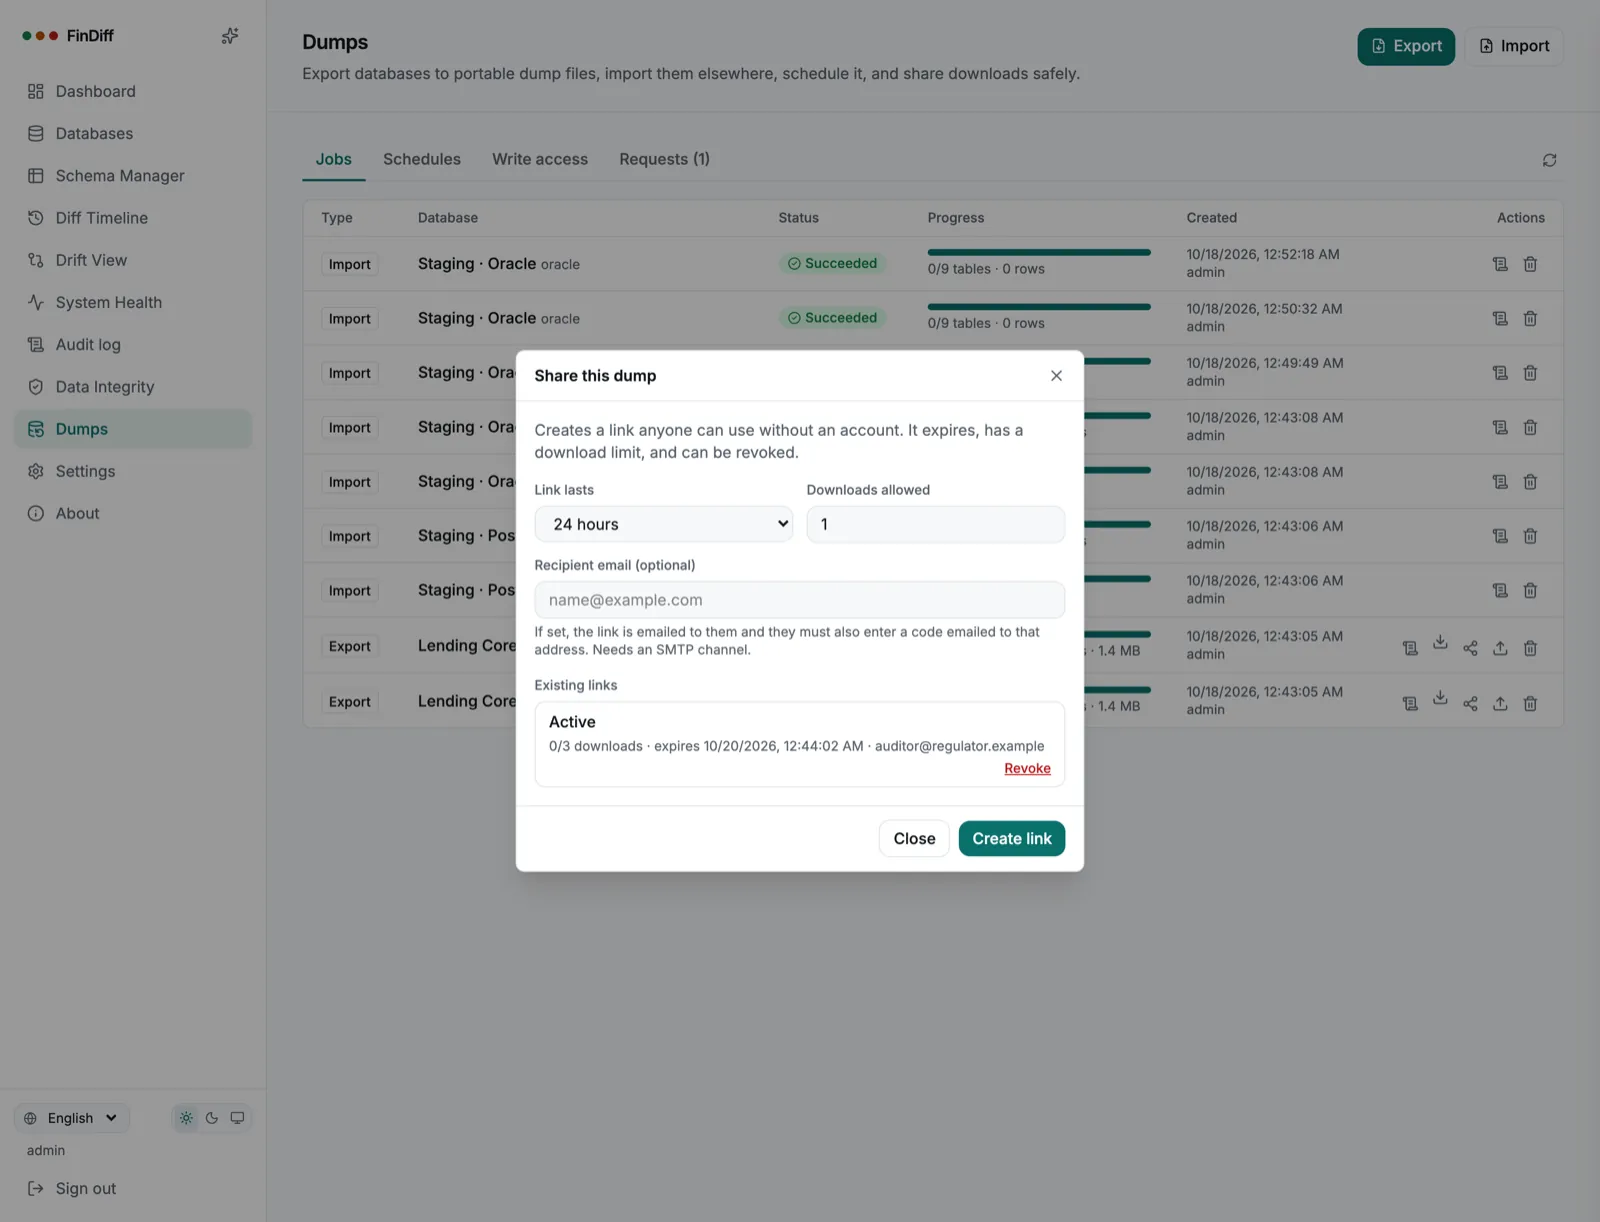
An administrator creates a link from a finished export: lifetime (default 24 hours, at most 7 days), downloads allowed (default 1, at most 20), revocable at any time. The token is shown once; only its hash is stored. Enter a recipient email and the link is mailed to them, and they must also type a 6-digit code mailed to that address (valid 10 minutes, 5 attempts). That needs an enabled SMTP channel (Alerts). Every download is written to the audit log.
Set FINDIFF_PUBLIC_URL so links carry the right address behind a proxy. The recipient needs no account; the page shows what the dump contains, when it expires and how many downloads remain.
Share requests (approval)
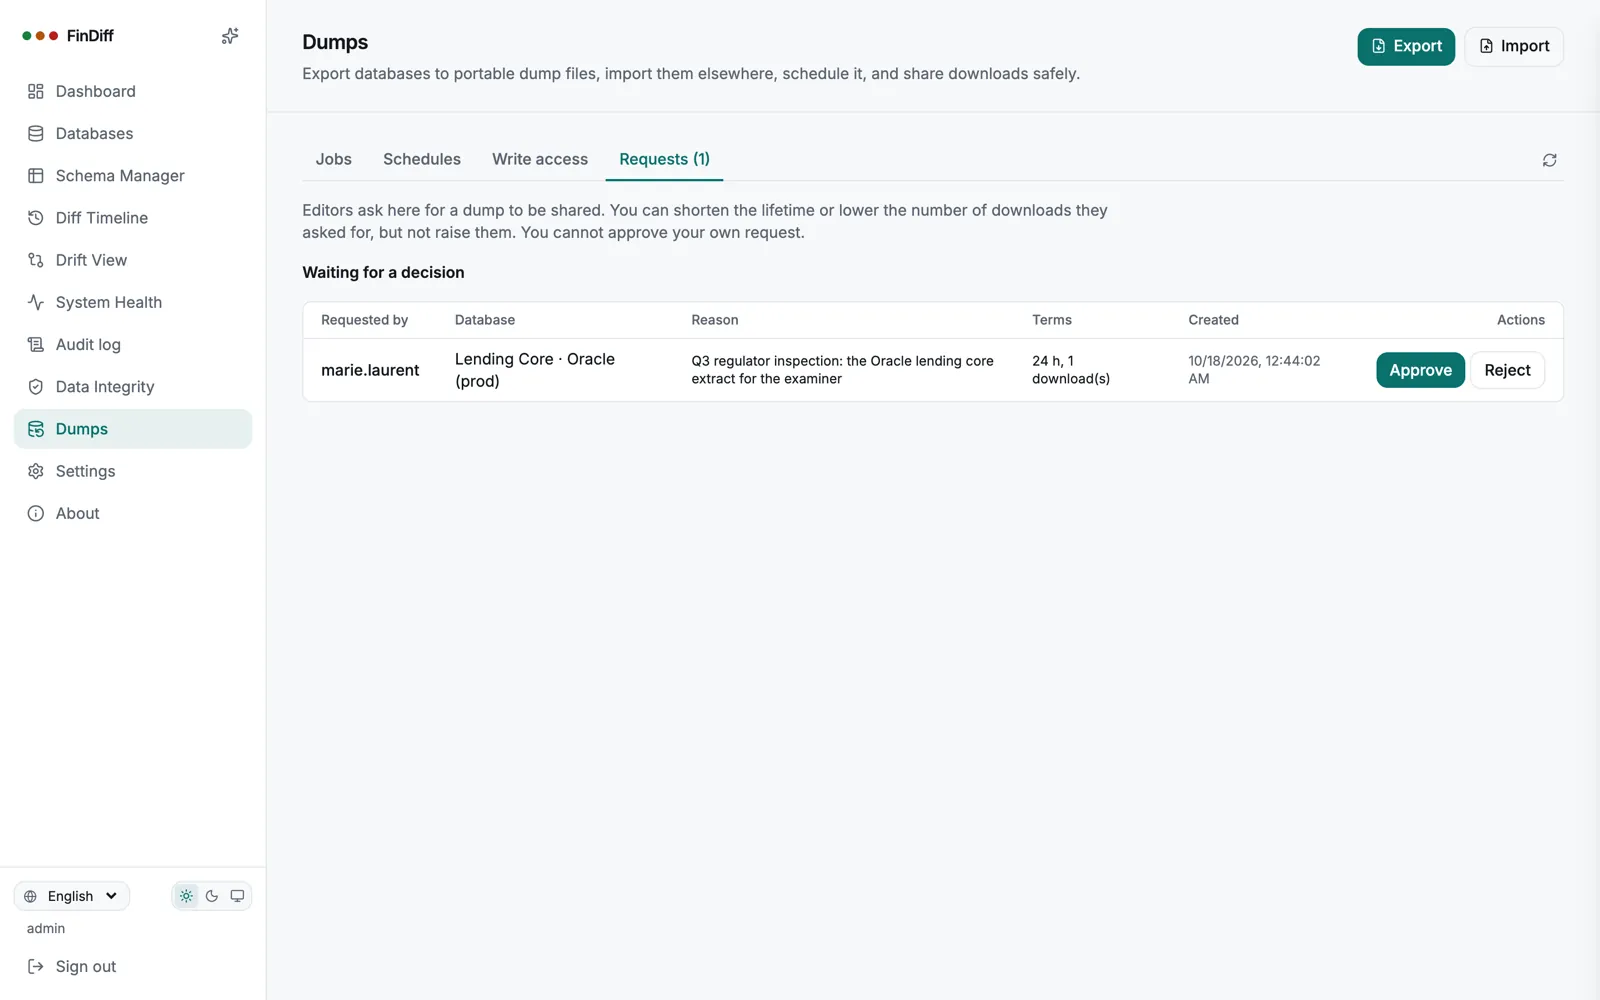
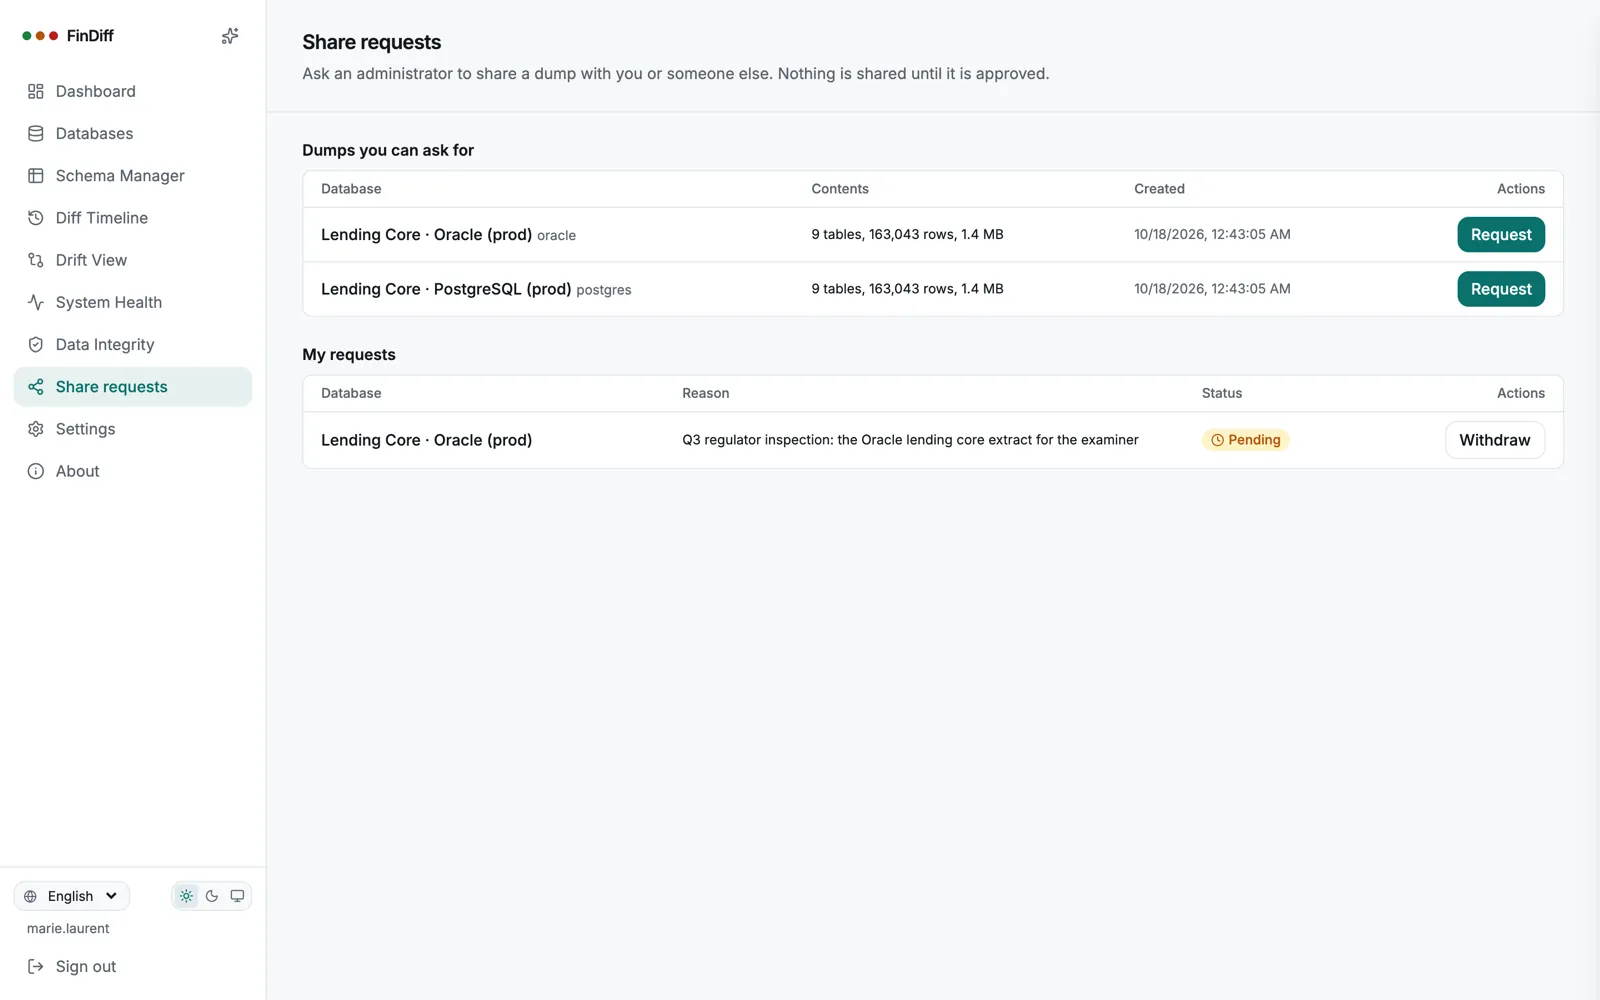
Editors cannot see or download dumps. The Share requests page lists them as metadata only and lets an editor ask for one, with a required reason and the lifetime and downloads they want. An administrator decides under Dumps → Requests: they may shorten the lifetime or lower the downloads, never raise them, and cannot approve their own request. Approval creates the normal link; if a recipient was named it goes to them behind the emailed code, otherwise it is sealed for the requester, who reveals it once. Requests, decisions and reveals are in the audit log; the link itself is not.
Anonymise a dump
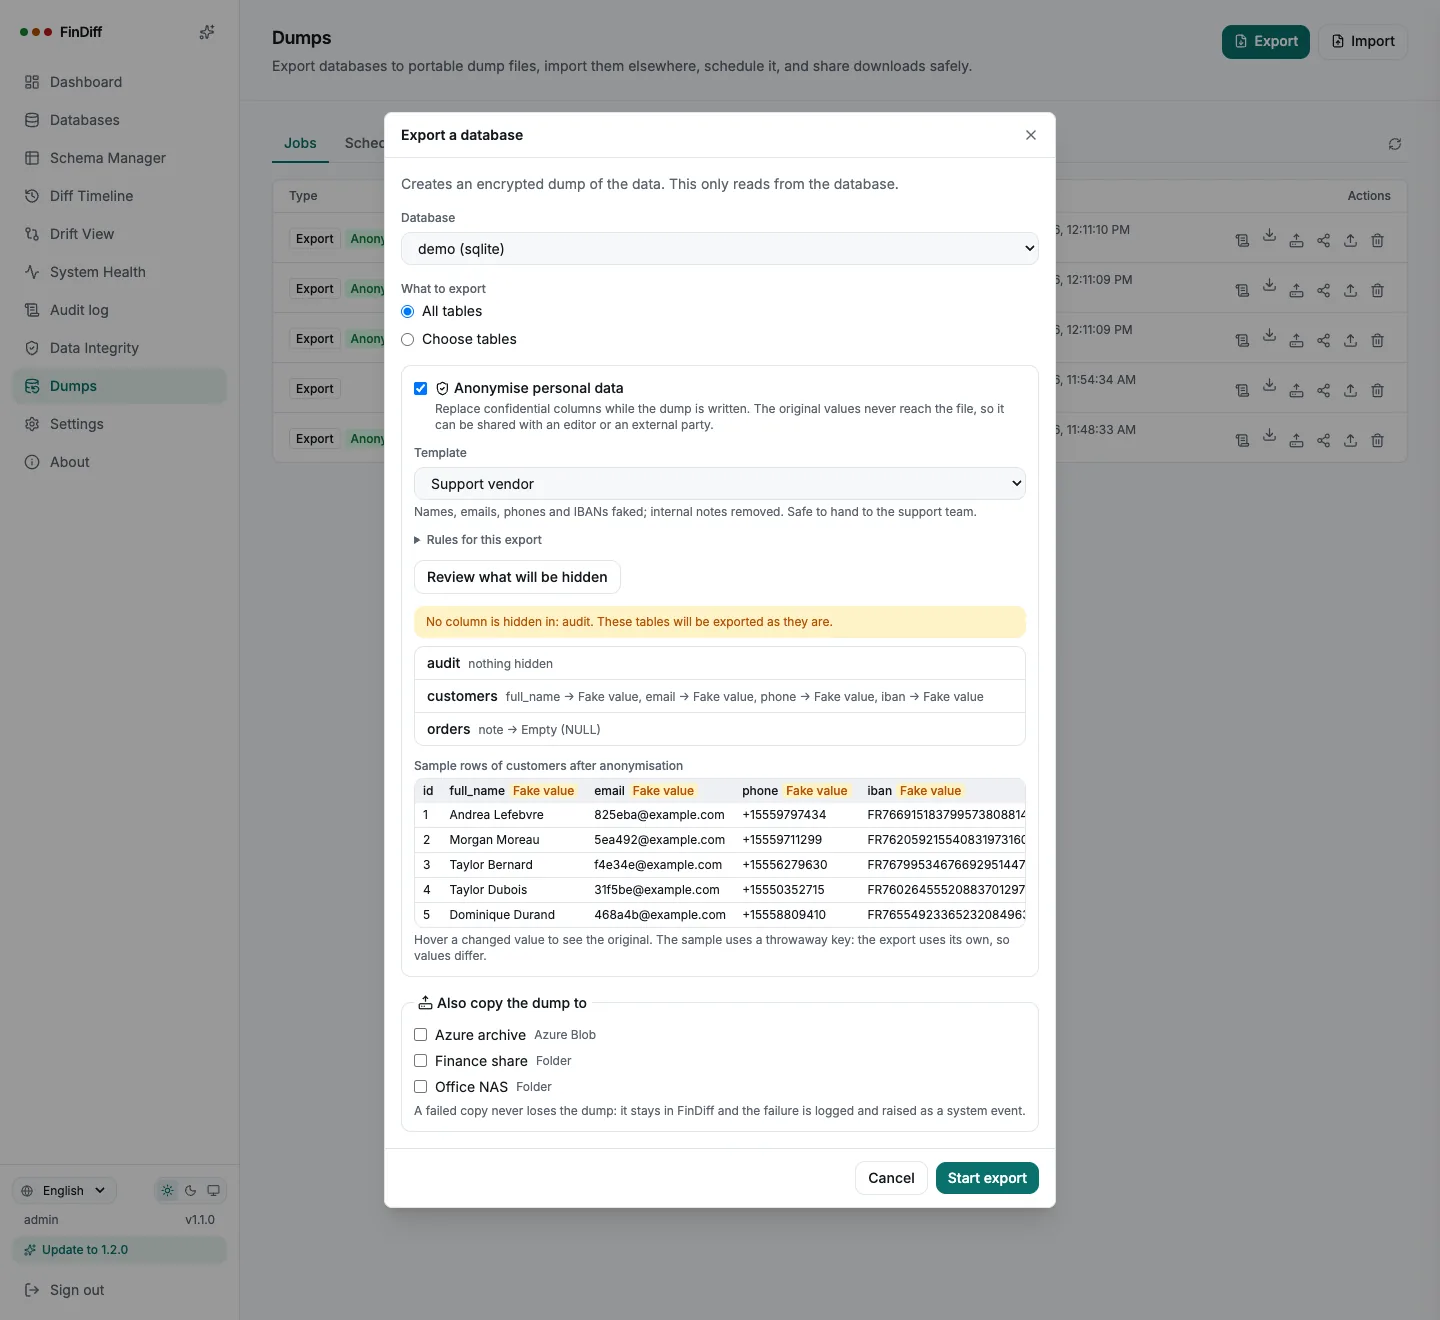
To give a dump to an editor, a vendor or an auditor without the personal data, tick Anonymise personal data in Dumps → Export (or in an export schedule). Matching columns are replaced while the dump is written, so the original values never reach the file.
Rules
A rule has a table pattern (empty means every table), a column pattern, and an action. Patterns accept * and commas (email,*_email) and ignore case. The first matching rule wins, so put exceptions first.
Action
Result
Fake value
A realistic value: name, first or last name, email (…@example.com), phone, IBAN, company, city. Deterministic, never taken from a list of real people.
Hash
A replacement of the same type and a length that still fits the column. Integers are mapped one-to-one within their digit count, so a hashed key never collides. Dates are shifted by up to a year.
Mask
Stars, keeping the last N characters (a value shorter than N is fully masked).
Empty (NULL) / Fixed value
Replaced by NULL or by one value. Refused on primary-key columns, because rows would collide.
Keep
Leaves the column as it is, to exempt it from a broader rule.
The same input gives the same output within one export, so foreign keys and joins still match. Each export uses its own random salt that is kept nowhere, so a pseudonym cannot be recomputed or matched against another dump. NULL stays NULL.
Templates
Dumps → Templates holds named rule sets. A built-in Personal data template matches common column names (email, phone, iban, names, passwords and tokens, birth dates). Copy it to adapt it, or write your own. A template is applied by name at export time, so a schedule picks up later edits, and a template used by a schedule cannot be deleted.
Check before you share
Review what will be hidden lists each table and the action every column gets, warns about tables where nothing is hidden, and shows five real sample rows after anonymisation (hover a value to see the original). The job list shows an Anonymised badge, and the dump header records it.
This is not a formal anonymisation guarantee: free-text columns that happen to contain personal data need a rule of their own. Always review the list against your real column names.
Storage destinations
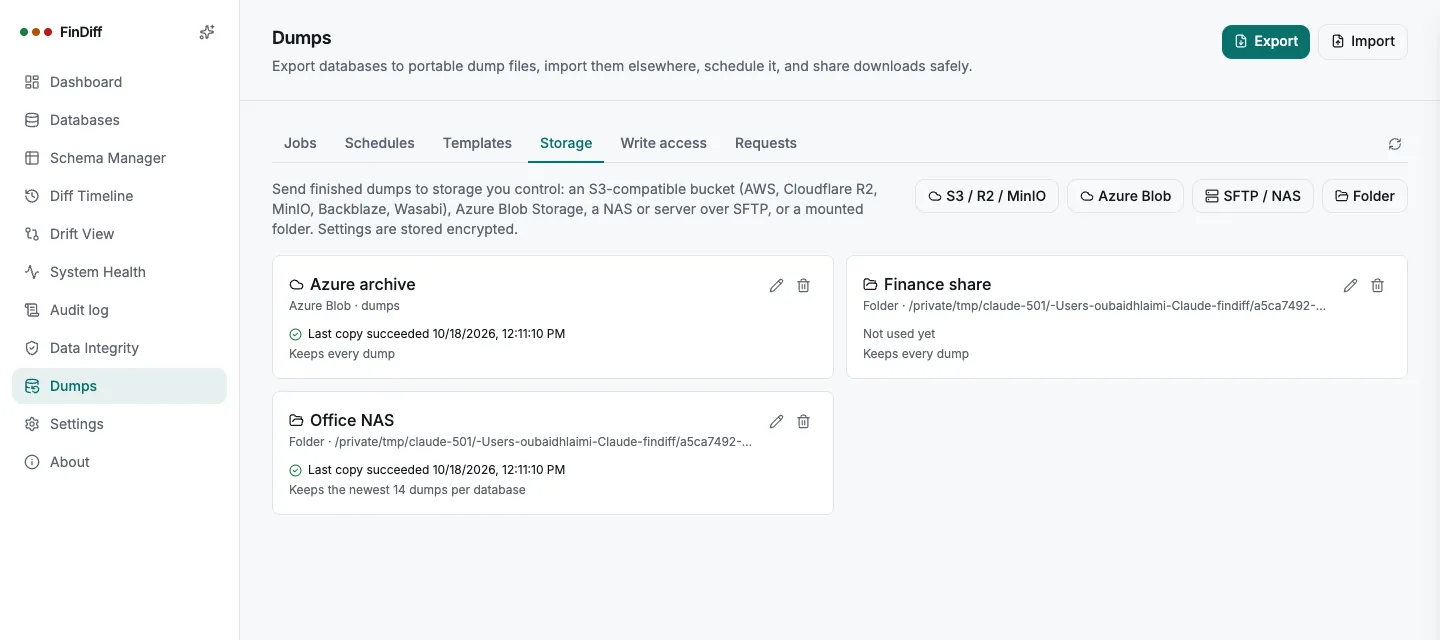
Dumps → Storage holds places finished dumps are copied to. Pick one or several in an export or an export schedule, or use Copy to storage on any finished dump (it runs as its own job with a log).
Kind
What you enter
S3-compatible
Bucket, access key, secret key. Endpoint for anything that is not AWS (Cloudflare R2 https://<account>.r2.cloudflarestorage.com, MinIO, Backblaze, Wasabi); region for AWS; tick path-style for self-hosted servers.
Azure Blob
Storage account, account key, container.
SFTP / NAS
Host, port, user, and a password or an unencrypted private key. Most NAS devices offer SFTP. The server's host key is pinned the first time you save and a different key later stops the transfer.
Folder
An absolute path inside the container, for a mounted share. In Docker, mount the share as a volume.
Files land in <folder>/<database>/<database>-<UTC time>[-anonymised].fdump.
A destination is saved only after a real test: FinDiff writes, lists and deletes a probe file. Test connection runs it without saving.
Settings are stored encrypted with FINDIFF_MASTER_KEY; secrets are never sent back to the browser (the form shows unchanged).
Keep the newest removes older dumps of the same database from the destination (it needs delete rights). 0 keeps everything.
A failed copy never loses the dump: it stays in FinDiff, the job log says what failed, the destination shows its last error, and a DUMP_UPLOAD_FAILED system event is raised.
A destination used by a schedule cannot be deleted. Everything here is administrator-only and written to the audit log.
Security: dumps are copied decrypted, as a download would be, so they can be imported anywhere. Use a private location, and anonymise the dump if the place is shared. Not included: client-side encryption with a passphrase, resumable uploads, SSE/KMS options, SFTP keys protected by a passphrase.
Oracle
Oracle works like every other engine, with a few specifics worth knowing before you connect.
Connecting
Use Add database → Oracle and enter host, port, and either a Service Name or a SID: they are different things. For a container database use the PDB service name (for example FREEPDB1 on Oracle 23ai Free).
CREATE USER findiff_reader IDENTIFIED BY "...";
GRANT CREATE SESSION TO findiff_reader;
-- the generator under Databases creates these for the tables you map:
GRANT SELECT ON APP.TBL_LOANS TO findiff_reader;
FinDiff lists every table the user can see, except those of Oracle-maintained schemas (SYS, SYSTEM, XDB, MDSYS and so on) and recycle-bin objects. If one user can see several application schemas, select tables per schema in exports.
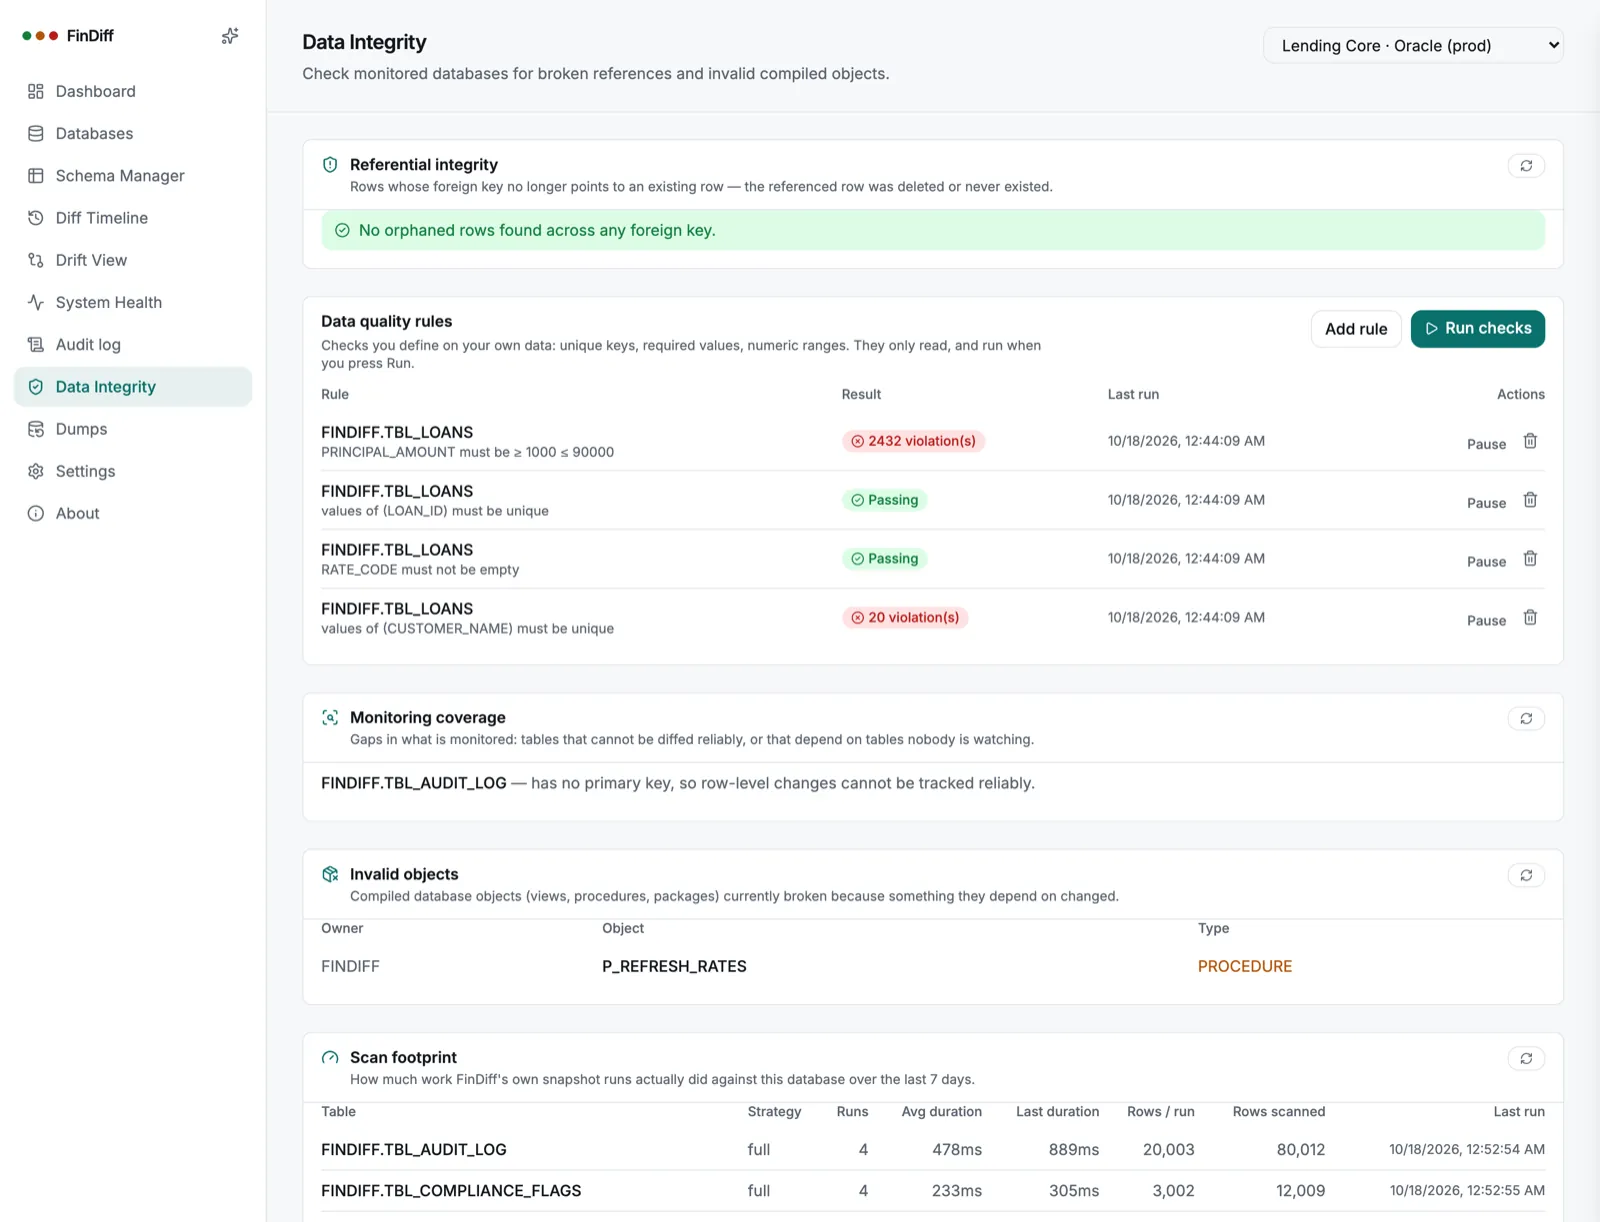
Invalid objects (Data Integrity) lists invalid procedures, views and packages that the user can see, so grant EXECUTE or SELECT on them if you want them watched. Oracle-maintained objects are excluded.
Incremental scanning uses the ORA_ROWSCN pseudo-column and needs no schema change; row-level granularity needs ROWDEPENDENCIES on the table, otherwise block-level is used and still correct.
Dumps
A dump from schema A loads into schema B when the table names match. Dumps spanning several source schemas with the same table names are refused by the dry run, before anything is written.
An empty string loads as NULL (Oracle’s own rule). Identity columns and sequences are not advanced after an import.
Write connection: the schema owner is the simplest; otherwise grant SELECT, INSERT, DELETE per table.
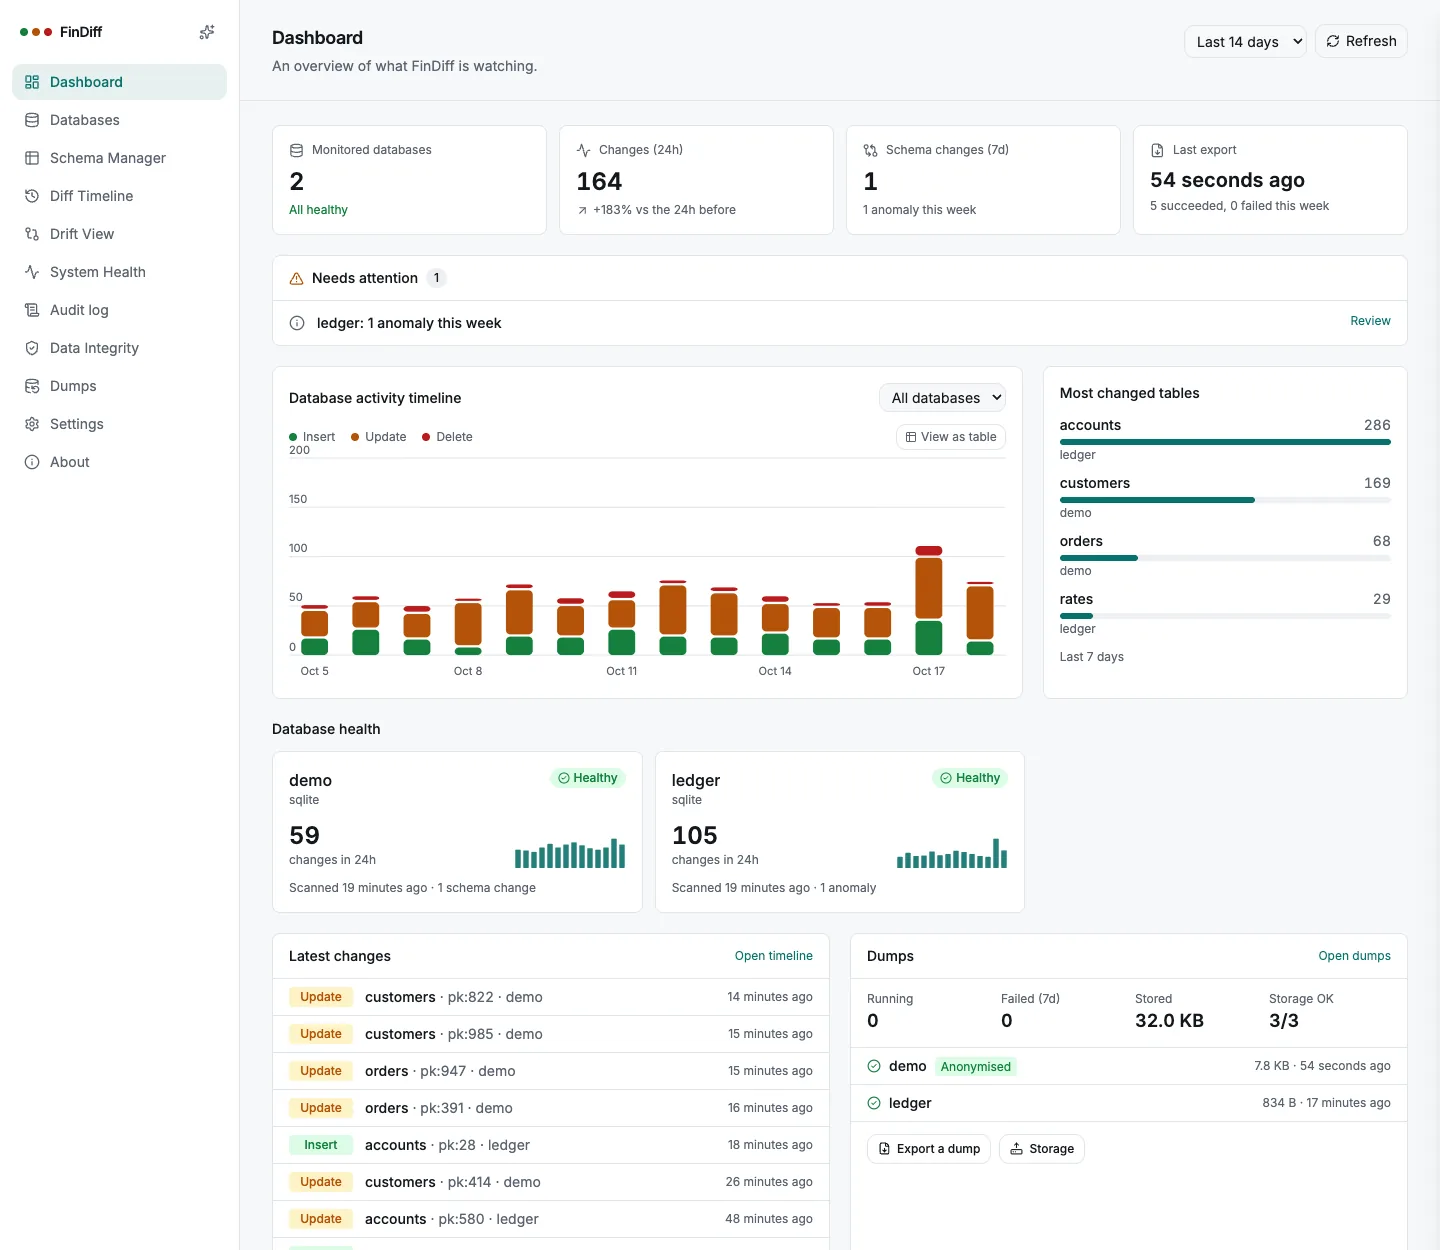
Dashboard
Key figures: databases and how many need attention, changes in the last 24 hours with the trend against the 24 hours before, schema changes and anomalies, and (administrators) the last export.
Needs attention, most severe first: a database never scanned or not scanned for three snapshot intervals (at least 10 minutes), failed scans in 24 hours, anomalies, failed dump jobs, failing schedules or storage destinations, pending share requests. Paused databases are never flagged.
Activity for all databases or one, over 7, 14 or 30 days; the most changed tables; a health card per database (Healthy, Warning, Failing, Paused) with a daily sparkline.
Dumps panel (administrators only, because dumps hold customer data): running and failed jobs, stored size, storage health, last export per database.
It refreshes every minute while the tab is visible and works on phones.
Users, roles and two-factor
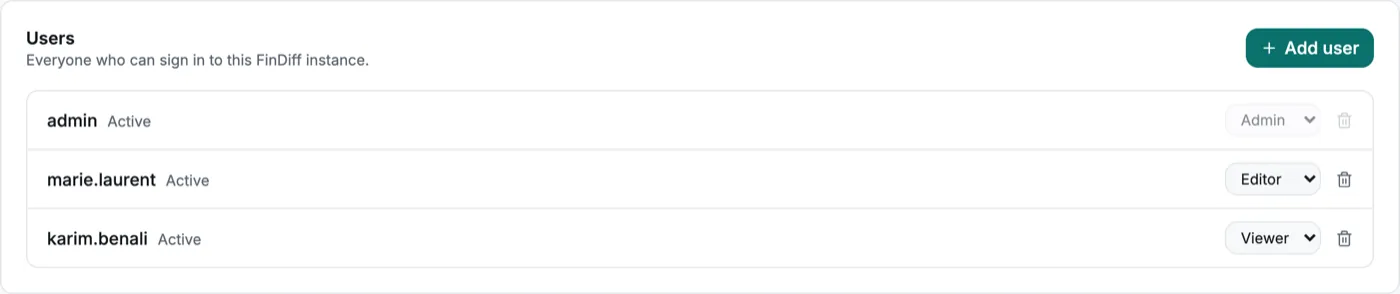
Create accounts under Settings → Users. Each has one role, enforced on the server and mirrored in the UI. New accounts default to viewer, and a new user must set their own password at first sign-in.
Role
Can do
viewer
Read history, mappings, reports, CSV export; use the AI Copilot. Cannot change anything.
editor
Viewer plus snapshots, connection tests, metadata scans, integrity and drift checks, edit mappings, groups and expected changes, review changes, ask for a share link.
admin
Editor plus users and roles, monitored databases, settings, Dumps (export, import, schedules, share, approve), audit log, backup.
The bootstrap admin always stays admin, nobody changes their own role, and the last admin cannot be demoted. Role changes apply immediately.
Two-factor authentication (TOTP)
Settings → Two-factor authentication: scan the QR code with any authenticator app and confirm a 6-digit code. Sign-in then asks for the code. An administrator can reset a user’s second factor. Single-sign-on accounts use their provider’s second factor instead.
Audit log
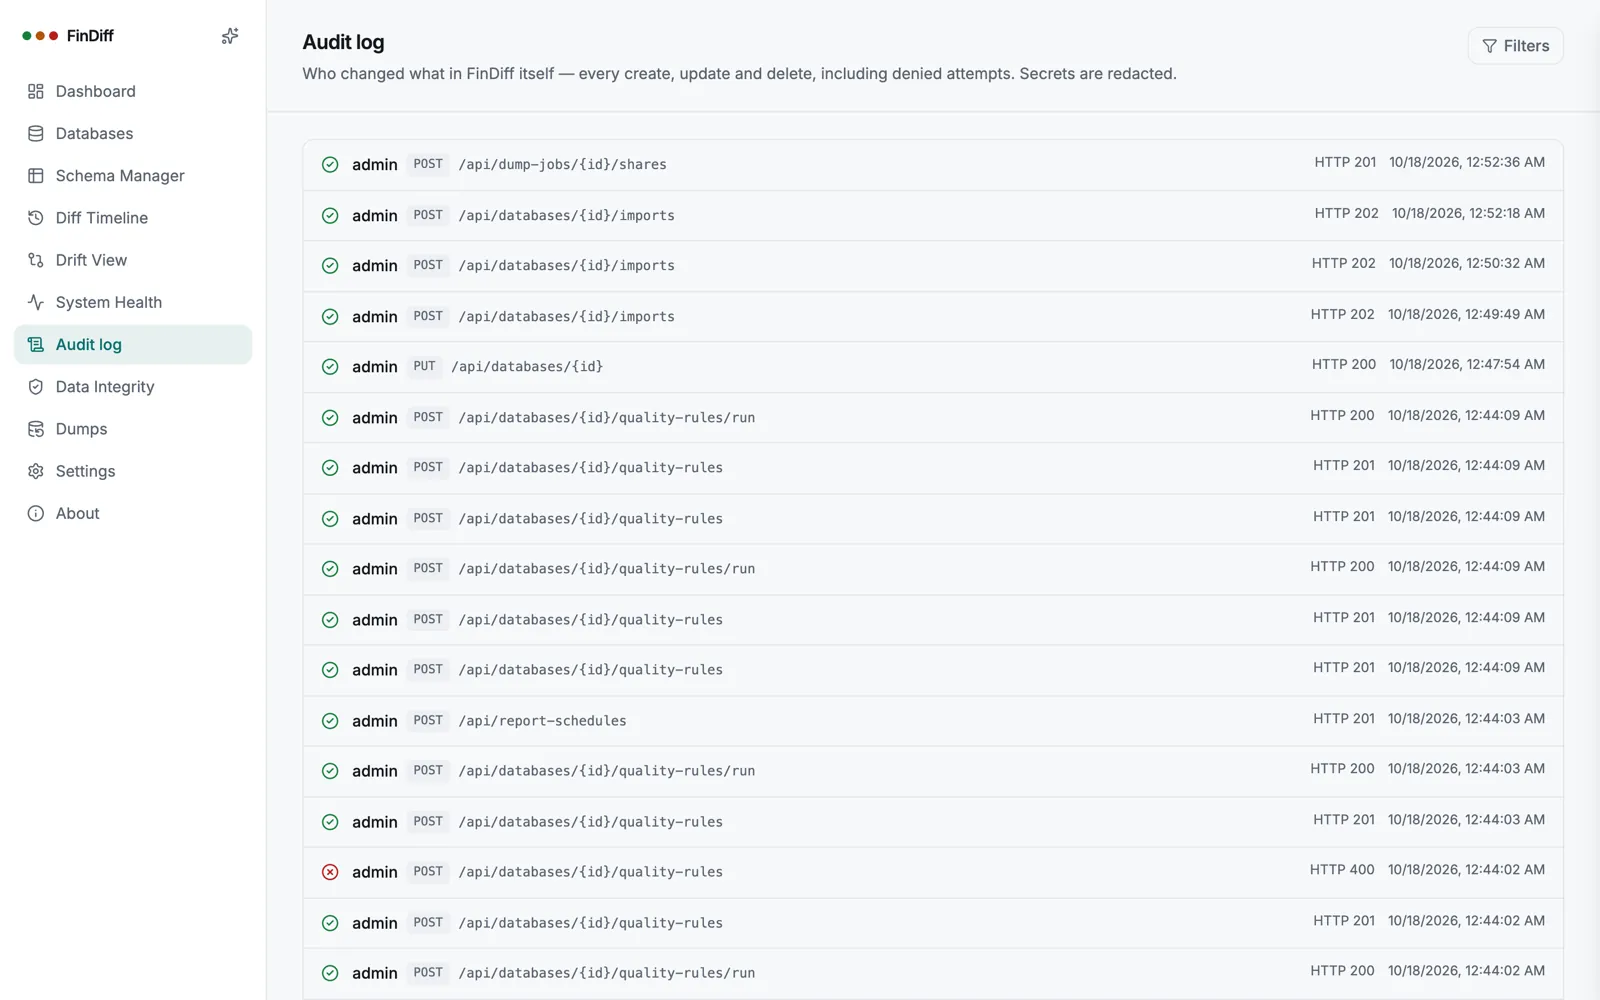
Administrators see who changed what in FinDiff itself under Audit log: actor, route, status and the request body with secrets redacted. Denied attempts are recorded. It is not pruned by retention.
Single sign-on (OpenID Connect)
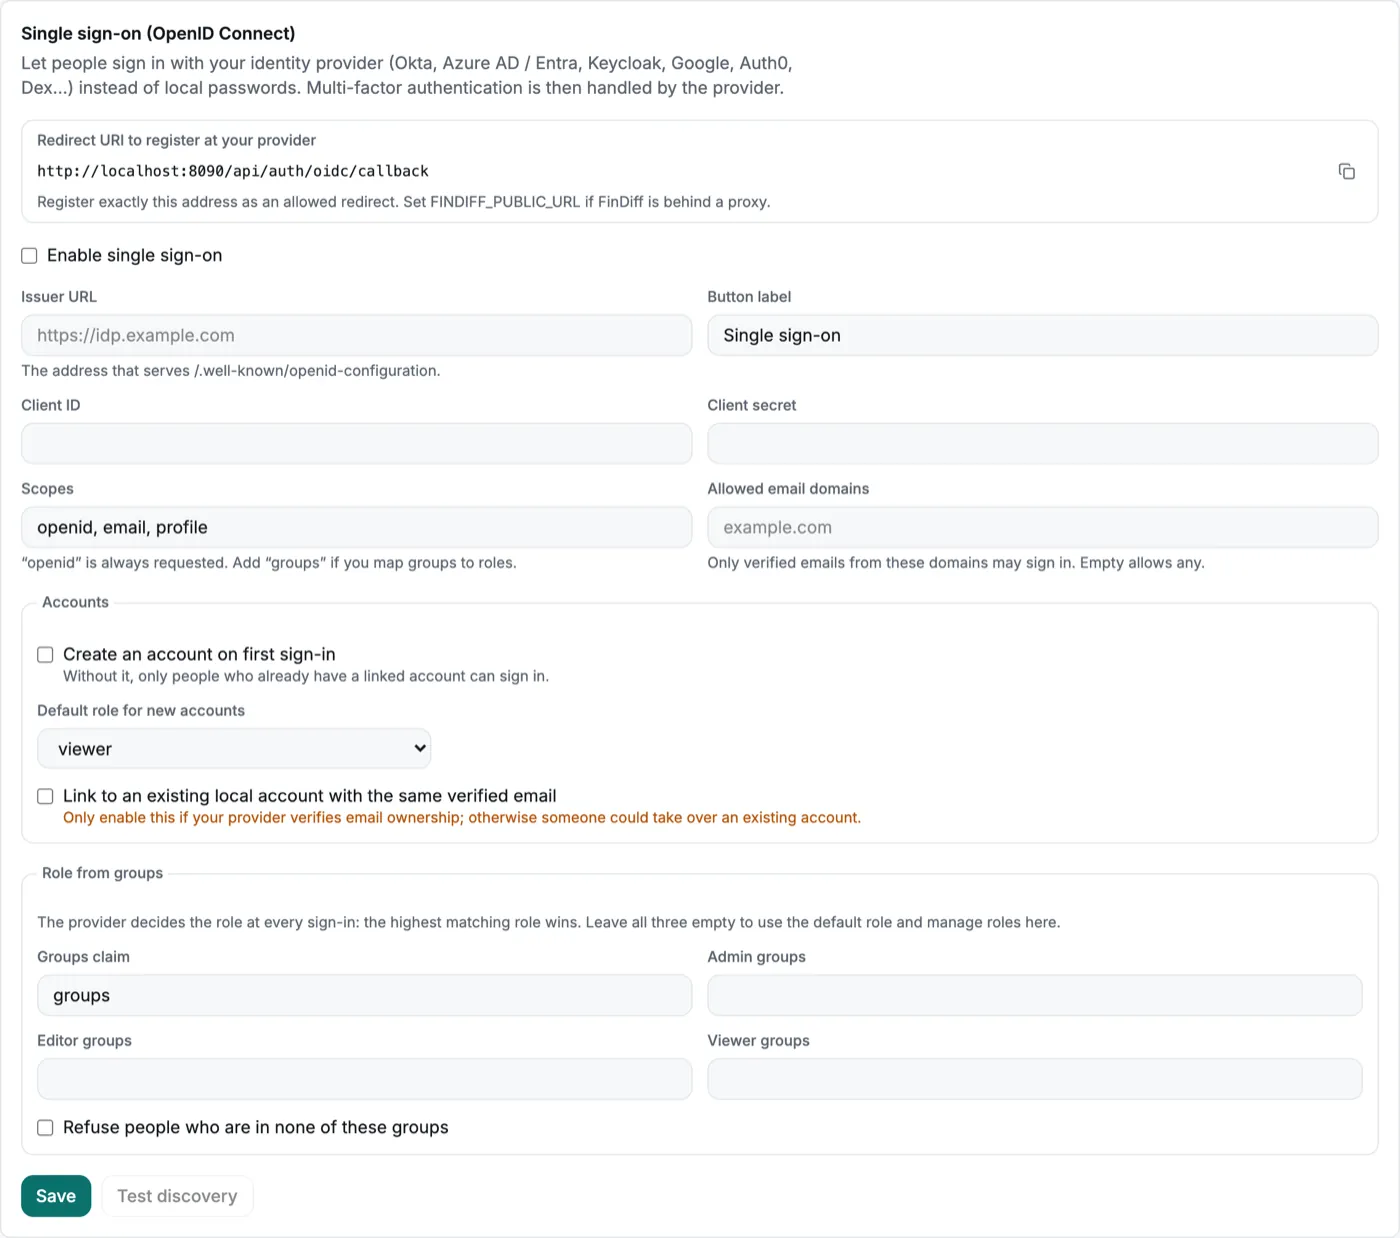
Let people sign in with Okta, Entra ID (Azure AD), Keycloak, Google, Auth0, Dex or any provider that publishes /.well-known/openid-configuration. FinDiff uses the Authorization Code flow with PKCE and a confidential client.
At your provider, create an OIDC web application and register the redirect URI shown on the settings page: https://<your-host>/api/auth/oidc/callback. Behind a proxy set FINDIFF_PUBLIC_URL=https://<your-host> so exactly that address is used.
Settings → Single sign-on: issuer URL, client ID, client secret. Press Test discovery, tick Enable, save. A button appears on the login page; password login keeps working beside it, so keep the bootstrap admin as a break-glass account.
Setting
Meaning
Scopes
openid is always requested. Add groups if you map groups to roles.
Allowed email domains
Only verified emails from these domains may sign in. Empty allows any.
Create an account on first sign-in
Off: only people who already have a linked account can sign in. On: new accounts get the default role.
Link to an existing local account
Off by default. Linking by email is an account-takeover route unless the provider verifies emails, so it needs a verified email and your explicit opt-in.
Role from groups
Map provider groups to admin, editor and viewer (highest match wins). The provider then decides the role at every sign-in. Empty uses the default role.
Refuse people in none of the groups
Deny sign-in when no group matches.
Not included: LDAP, SAML, single logout and refresh tokens (sessions are FinDiff’s own 24-hour sessions). SSO accounts have an unusable random password.
Alerts and scheduled compliance reports
Alert channels
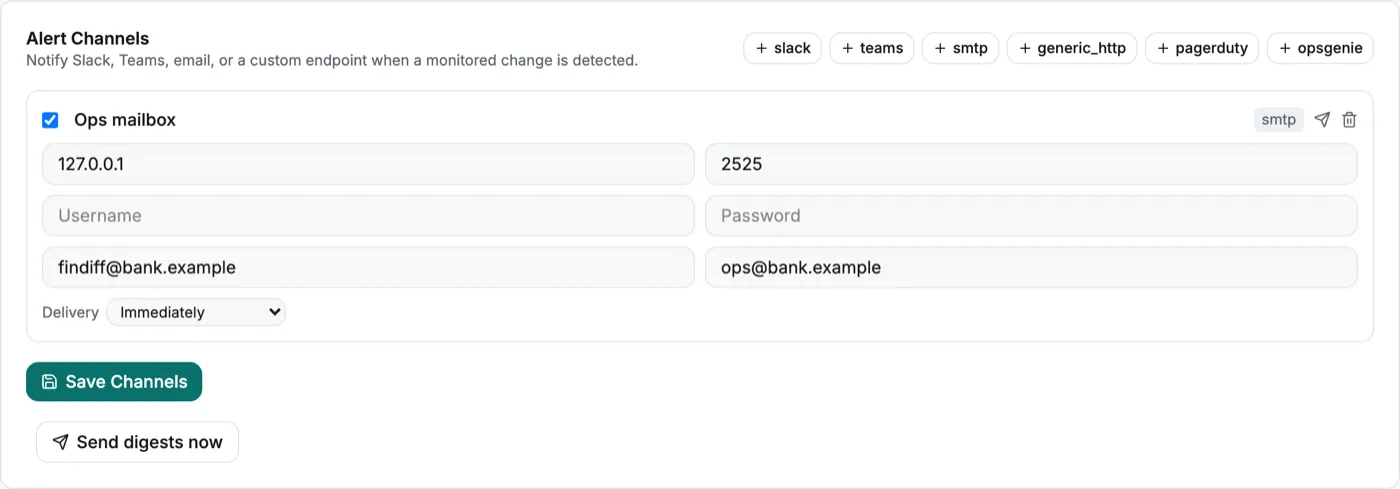
Settings → Alert channels: add Slack, Teams, SMTP email, a generic HTTP webhook, PagerDuty or Opsgenie. Each is independent and can deliver immediately or in a digest. Alert rules route changes to specific channels by database or table.
SMTP
An enabled SMTP channel is also what sends share-link emails and codes and the scheduled compliance reports. Fill in host, port, optional username and password, the from address and recipients.
Scheduled compliance reports
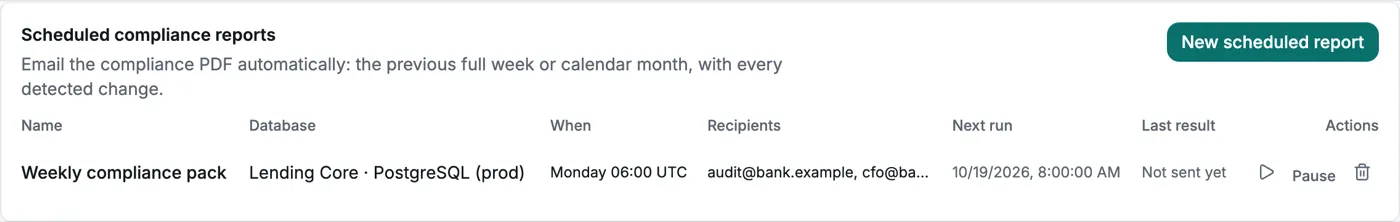
Settings → Scheduled compliance reports (administrators): choose a database, weekly (a weekday) or monthly (day 1 to 28), an hour in UTC and recipients. Each run covers the previous full period, so consecutive reports never overlap or leave a gap, even if the server was down and sent one late. The PDF is attached; a period with no changes is still sent, as evidence of absence. Send now sends the current period without moving the cadence. Creating a schedule without an SMTP channel is refused with a clear message.
Data quality and coverage
Data Integrity checks what is stored, not only what changed.
Referential integrity: rows whose foreign key no longer points to a row.
Data quality rules: unique (one or several columns; NULLs ignored), not null, and numeric range (min and/or max). Rules run when you press Run checks and report the number of violations; a rule that cannot run says Could not run, never a pass. Everything is a read-only COUNT.
Monitoring coverage: tables without a primary key (their row-level changes cannot be tracked reliably) and tables that depend on unmonitored tables.
Invalid objects: Oracle only; other engines say so.
Change feeds for very large tables
By default FinDiff pages through a table and compares checksums. For a table too large to rescan, a table can read an exact change feed instead. This is opt-in and set up by your DBA; FinDiff issues no DDL. Set the strategy per table in Schema Manager (or PUT /api/table-mappings/{id}/scan-settings). The first run is a normal baseline scan. If the feed cannot be used, FinDiff does a full scan and records a CDC_FEED_FALLBACK system event.
PostgreSQL: pg_logical
wal_level = logical (restart required) and a free replication slot.
Create a slot named findiff_<database name> with the built-in plugin: SELECT pg_create_logical_replication_slot('findiff_mydb', 'test_decoding');
A login role with the REPLICATION attribute and SELECT on the monitored tables. This makes it not strictly read-only at the server level; FinDiff still only runs SELECT and the slot functions.
A replication slot holds write-ahead log until it is confirmed. FinDiff confirms it after every run and warns (CDC_SLOT_LAG) above 1 GB. If you stop using FinDiff, drop the slot (SELECT pg_drop_replication_slot('findiff_mydb');) or the source disk will fill.
MySQL and MariaDB: mysql_binlog
log_bin on and binlog_format=ROW (MySQL 8 defaults; MariaDB needs both set).
A login with REPLICATION SLAVE, REPLICATION CLIENT and SELECT on the monitored tables.
Position-based: the server keeps nothing for FinDiff, so there is no slot to forget. If FinDiff is stopped longer than binlog_expire_logs_seconds it does one full scan.
SQL Server and Oracle
SQL Server uses native Change Tracking (mssql_change_tracking, enable it per table; it also detects deletes). Oracle uses ORA_ROWSCN with no schema change. Any engine can also use a watermark column.
Secrets and TLS
Connection strings are stored encrypted, and you can avoid storing a password at all by referencing it:
postgres://app:${file:app_db_password}@db:5432/app        # a file in the secrets directory
postgres://app:${env:FINDIFF_SECRET_APP_PW}@db:5432/app   # an environment variable
${file:NAME}: a plain file name inside FINDIFF_SECRETS_DIR (default /run/secrets). Slashes, .. and symlinks leaving the directory are refused; a trailing newline is stripped.
${env:NAME}: only variables named FINDIFF_SECRET_*. This is deliberate: editors can edit connection strings, and an unrestricted reference could read FINDIFF_MASTER_KEY back through an error.
References are resolved each time a connection opens, so rotating a secret needs no change in FinDiff. Works with Docker and Compose secrets, Kubernetes secret volumes and vault-agent files, for monitoring and for write connections.
TLS to your databases
TLS is whatever the driver’s connection-string options say; FinDiff adds no TLS layer of its own. For PostgreSQL use sslmode=verify-full&sslrootcert=/path/ca.crt in production (verified against a real server with a private CA). MySQL, SQL Server and Oracle TLS options pass through to the driver but have not been exercised. FinDiff itself does not terminate TLS: put it behind a reverse proxy.
Health, metrics and backup
Probes
GET /api/livez (process is serving) and GET /api/readyz (local store answers). Both are unauthenticated, for Docker and Kubernetes. The image already carries a healthcheck on /api/livez.
Prometheus metrics
GET /api/metrics returns 404 unless FINDIFF_METRICS_TOKEN is set; then it needs Authorization: Bearer <token>.
Series include findiff_up, findiff_monitored_databases{state}, findiff_diff_events_24h{change_type}, findiff_scan_runs_24h{result}, findiff_last_scan_timestamp_seconds, findiff_app_events_1h{severity} and findiff_http_requests_total{code}. A useful alert: time() - findiff_last_scan_timestamp_seconds > 3600.
Backing up FinDiff itself
All state (users, mappings, settings, history, audit log, dump records) is in one SQLite file, findiff.db in FINDIFF_DATA_DIR. Settings → Backup → Download backup (or GET /api/admin/backup as admin) gives a consistent snapshot while FinDiff runs. To restore: stop FinDiff, place the file at $FINDIFF_DATA_DIR/findiff.db (delete stale -wal and -shm files), start with the same master key.
Not in that backup: the dump files in $FINDIFF_DATA_DIR/dumps and Copilot uploads in ai_uploads. Back those folders up separately if you need them. The master key is not in the backup either and is required to read connection strings and dump files.
Updating FinDiff
Latest release: v1.1.1, published 2026-10-18. The same number is in About → Version inside the app, which also tells you which version you are running.
How you are told
FinDiff checks this site's latest.json shortly after it starts and then twice a day. When a newer release exists, administrators see a banner at the top of the app, every user sees an Update to x.y.z note in the sidebar next to the version number, and About → Version shows the release notes. Dismissing the banner hides it until the next release.
What is sent: one plain GET for that public file, with a User-Agent that names your version (FinDiff/1.1.0). No account, database, host name or installation id leaves your network. Set FINDIFF_UPDATE_CHECK=false to turn it off completely.
How to update
docker compose pull
docker compose up -d
Your data, keys and dumps live in the mounted volume and are kept. Database migrations run automatically at start. Before a big jump, download a backup from Settings → Backup, and keep the same FINDIFF_MASTER_KEY. To pin a release instead of following latest, use the tag, for example oubaidhl/findiff:1.1.0.
Upgrading from an image older than 1.1, or the container exits with attempt to write a readonly database? Since 1.1.0 the server runs as an unprivileged user, and a data volume created by an older image belongs to root. Version 1.1.0 failed on such a volume; 1.1.1 repairs the ownership of the data folder automatically at start and then drops to the unprivileged user, so docker compose pull && docker compose up -d is enough. If the repair is not allowed (some NFS exports), the log says so: make the folder writable for uid 10001.
Running without Compose: docker pull oubaidhl/findiff:latest, then stop and re-create the container with the same volume and environment.
Troubleshooting
Symptom
Cause and fix
Import is disabled for a database
It has no write connection. Add one under Dumps → Write access.
Dry run: “no such table in the target”
Tick Create tables that do not exist to create them from the dump (same engine, dump exported with the current version), or tick “Skip tables that do not exist”.
Dry run: “would both be loaded into …”
The dump spans several source schemas with the same table names (typical on Oracle). Re-export a single schema by selecting its tables.
Replace fails on a foreign key
Dumps exported by an older version, or from a role that could not read foreign keys, may be in the wrong order. Re-export with the current version, and make sure the monitoring role can see the keys.
Share link shows a wrong address
Set FINDIFF_PUBLIC_URL to the public address.
Recipient never gets the code
Share emails need an enabled SMTP channel. Check System Health for the send error.
SSO redirect mismatch
Register exactly the redirect URI shown in the settings and set FINDIFF_PUBLIC_URL behind a proxy.
Container cannot write /data
A bind mount must be writable by uid 10001.
Primary and foreign keys not seen on PostgreSQL
Fixed in the current version: keys are read from the catalog, so a SELECT-only role sees them. Update the image.
Oracle: Invalid objects lists nothing
The monitoring user only sees objects it has a privilege on. Grant access to what you want watched.
Settings → Single sign-on says it could not load
Fixed in the current version for fresh installs. Update the image.
Source disk filling on PostgreSQL
A forgotten replication slot. Drop it: SELECT pg_drop_replication_slot('findiff_<db>');
Trying it locally
Since FinDiff's source isn't published, "development" here means trying the app against a disposable database rather than building from source.
# a throwaway Postgres database
docker run -d --name findiff-demo-db \
  -e POSTGRES_PASSWORD=findiff \
  -e POSTGRES_DB=findiff_demo \
  -p 5433:5432 \
  postgres:16

# FinDiff itself, pointed at a scratch data directory
docker run -d --name findiff-dev \
  -p 8080:8080 \
  -e FINDIFF_MASTER_KEY="$(openssl rand -base64 32)" \
  -e FINDIFF_ADMIN_USERNAME=admin \
  -e FINDIFF_ADMIN_PASSWORD=devpassword \
  -v findiff_dev_data:/data \
  oubaidhl/findiff:latest
Add the throwaway database using host host.docker.internal, port 5433, database findiff_demo. Scan its schema, map a table, insert a few rows, snapshot, mutate a row, snapshot again, and watch the change land in the Diff Timeline.
Scaling to large tables
FinDiff pages through tables by primary key rather than loading them whole, so scanning stays bounded regardless of table size. Most engines get a single-round-trip checksum that detects an unchanged table with zero row data transferred. Storage for known rows is kept per distinct row, not per snapshot, so repeated scans of an unchanged table don't multiply what's stored.
For a very large or very active table, configure a watermark column, or on Oracle and SQL Server, native incremental scanning, from that table's settings in Schema Manager. Both are strictly opt-in and read-only; FinDiff never issues DDL against a monitored database.
FAQ
Does FinDiff ever write to my database?
Monitoring never does. A statement guard rejects anything that isn't SELECT, read-only transactions are used where the driver supports them, and we recommend connecting with a database-level read-only role as an independent third layer. The only thing that writes is dump import, which is off until an administrator adds a separate write connection to a database, runs in one transaction and asks for a typed confirmation on replace.
Can I use a fully local, offline AI model?
Yes. The AI Copilot works with Ollama, LM Studio, or any other OpenAI-compatible local server, no data has to leave your network unless you choose a cloud provider instead.
Is the source code available?
FinDiff ships as a versioned Docker image so every install is a tested build. The community repository carries the documentation and is where issues and feature requests are welcome.
Can more than one person use the same instance?
Yes. Administrators create accounts under Settings → Users with a role (viewer, editor or admin), and you can add single sign-on and two-factor authentication. See Users, roles and two-factor.
What happens if I lose the master key?
Every stored connection string and every stored dump file becomes permanently unrecoverable: you would re-add each database with a new key. Back this value up separately from the data directory.
Can I import a dump into a different engine?
No. Import is same-engine for now (PostgreSQL into PostgreSQL, Oracle into Oracle). Cross-engine type mapping is not supported.
Does importing into a monitored database trigger alerts?
Yes: the next snapshot reports the imported rows as changes, which is correct. Pause alerts for the target, or acknowledge the batch afterwards.